

Researcher @GoogleDeepMind working on AI control and agent safety.
Mountain View
Joined October 2023
- Tweets33
- Following189
- Followers213
- Likes76






Pinned Tweet
Excited that our AI Control Roadmap is out. We built an internal monitoring system that reviews agent trajectories and classifies them against our threat taxonomy. We've now analyzed 1M+ coding agent tasks. Always happy to connect with others working on AI control and oversight!


Key takeaway: most flagged events aren't adversarial, but from agents misinterpretation or being overeager to hit a user's goal. That insight fed directly into the live monitors we built for Gemini Spark agents that catch things like unintentional data deletion in real time.
Long road to Gemma 4. Learned a ton from the people around me along the way. Huge congrats to the whole team, and can't wait to see what you build with it!


Ran into @lexfridman by chance earlier this week and finally sat down today. Perfect way to wrap up #NeurIPS. It’s been 6 years (how time flies!) since we worked together at MIT. Great catching up on life, ML, and old times.

Broke my Twitter silence for this one. 📸
Officially “UMass bros” according to the legend himself, so I’ll take it. 😎
#NeurIPS #NeurIPS2025

Thrilled to announce I’ve successfully defended my PhD! 🎓 Deeply grateful to my advisor Lee Spector, my committee @scottniekum, @MajiSubhransu, @jeffclune, and all collaborators, friends, and family. Milestone achieved, excited for the next chapter!


Li Ding retweeted

Preferences in RLHF often come from many people with differing values. Ryan's work explores how to infer a set of representative reward functions that captures that diversity, so that we can better reason about risk and fairness in these settings.

Excited to share our new paper on Pareto Optimal Preference Learning (POPL)! 🎉
POPL aims to better align AI with diverse human values by building diverse sets of reward functions or policies!
arxiv.org/abs/2406.15599v1
Work done with @li_ding_ , Lee Spector and @scottniekum

POPL enhances the safety and fairness of RLHF by aligning agents and LLMs with diverse human values. It effectively addresses hidden contexts in preferences, ensuring risk-sensitive alignment without additional labeling.
Led by @RyanBoldi, w/ Lee Spector and @scottniekum.
Excited to share our new paper on Pareto Optimal Preference Learning (POPL)! 🎉
POPL aims to better align AI with diverse human values by building diverse sets of reward functions or policies!
arxiv.org/abs/2406.15599v1
Work done with @li_ding_ , Lee Spector and @scottniekum
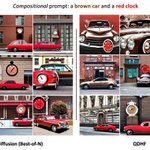
In a nutshell, new results highlight QDHF's strength in handling complex prompts for GenAI. While diffusion models often struggle with composing objects and attributes correctly, QDHF enhances diversity to explore various compositions, thus improving the quality of responses.

Special thanks to @andrewdai99 for insightful suggestions on the paper! As we prepare to share the latest version, check out our previous spotlight talk at NeurIPS @aloeworkshop: neurips.cc/virtual/2023/8378…, and the recent tutorial in @pyribs (w/ @btjanaka): docs.pyribs.org/en/stable/tu….
Exciting news! Our QDHF paper has been accepted at #ICML2024! Huge thanks to incredible coauthors: @jennyzhangzt, @jeffclune, Lee Spector, and @joelbot3000. Stay tuned for updates on arXiv with our latest findings!
Project website: liding.info/qdhf 👇
🚀Thrilled to release the QDHF tutorial in @pyribs! Big shoutout to @btjanaka for his meticulous editing and insightful feedback👏. Dive into the tutorial to explore how QDHF enhances GenAI models with diversified, high-quality responses and apply these insights to your projects!

Ecstatic to announce the release of @pyribs 0.7.1! The absolute highlight of this release is the QDHF (Quality Diversity through Human Feedback) tutorial contributed by @li_ding_! The tutorial is available here and runs on Google Colab in ~1 hour:
docs.pyribs.org/en/stable/tu…

ALT Images generated by QDHF for the prompt "an astronaut riding a horse on mars"
Had a great time yesterday presenting our QDHF work at #NeurIPS2023 @aloeworkshop! Fantastic workshop with great vibes. Glad to meet so many people in open-endedness, QD, RL, especially my amazing collaborators @jennyzhangzt and @jeffclune! (Thanks to @RyanBoldi for this photo!)

Hello #NeurIPS2023! I will present our work on Quality Diversity through Human Feedback tomorrow 12/15 at @aloeworkshop. Feel free to stop by Room 211-213 for our spotlight talk (4:15-4:30) or catch us during the poster session (12:45-1:45). Let's chat about learning and more!
Check out the QDHF project website: liding.info/qdhf/. We also released our code on GitHub: github.com/ld-ing/qdhf. Stay tuned for more updates in the upcoming weeks!
Li Ding retweeted

Thrilled to announce the first annual Reinforcement Learning Conference @RL_Conference, which will be held at UMass Amherst August 9-12!
RLC is the first strongly peer-reviewed RL venue with proceedings, and our call for papers is now available: rl-conference.cc.

Li Ding retweeted
Thrilled to announce the first annual Reinforcement Learning Conference @RL_Conference, which will be held at UMass Amherst August 9-12! RLC is the first strongly peer-reviewed RL venue with proceedings, and our call for papers is now available: rl-conference.cc. 🧵

Great work led by @RyanBoldi ! QD maintains diversity with pre-defined diversity metrics (or learned, e.g., QDHF!), but is it necessary? This paper proposes an alternative that uses MMO to solve deceptive RL tasks, and outperforms ME on QD-score w/o even optimizing towards it!
📢 New Paper Alert!
arxiv.org/abs/2311.02283
🔍 Navigating Deceptive Domains w/o Explicit Diversity Maintenance
Conclusion: Objectives are all you need!🚀
Authors: Me, @li_ding_ and Lee Spector
Accepted @ the #NeurIPS2023 Workshop on Agent Learning in Open Endedness
🧵👇

Good news: QDHF will be presented as a Spotlight at the NeurIPS 2023 ALOE workshop: sites.google.com/view/aloe20…. See you in New Orleans and let's chat!


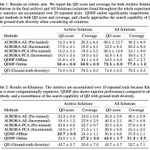
🚀Excited to share Quality Diversity through Human Feedback (QDHF): arxiv.org/abs/2310.12103. QDHF learns diversity metrics from human judgments of difference, and generates diverse and high-quality responses for tasks such as text-to-image generation. 1/
