

Your inference workstation.
Joined January 2026
- Tweets161
- Following30
- Followers1.6K
- Likes453




Pinned Tweet
1/ Today, we're excited to launch PFlash V2.
If you ask questions over long documents, retrieved passages or a whole codebase on one GPU, reading the prompt can be most of the wait before the first token.
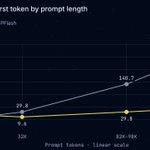
PFlash sits in front of the model and decides which parts of a long prompt the model actually reads. On six public long-context sets it answers 92 of 124 questions against full prefill's 94, while the model reads a median 27% of the prompt, and on one GPU the first token arrives 3.7× sooner on average.
Lucebox now makes images too.
MOSS-Image, a 5B text-to-image model, runs natively in our engine on the Radeon AI PRO R9700. A 1024x1024 image takes 2.7 s at 8 steps.
1.8x faster than ComfyUI on a DGX Spark with the same weights and settings.
In the video both start from the same noise, so they make the same images.
On a Lucebox the image model shares the R9700 with chat, and the two take turns on the card.
With Qwen 3.8 27B loaded beside it, an image takes 3.0 s. If a long chat reply pushed the image weights off the card, 4.1 s.

The engine is open source and answers OpenAI's images API. On a Lucebox it installs from Lucebox Manage, 15 GB in all.
Full blog post by @davideciffa: lucebox.com/blog/moss-image-…

Lucebox retweeted

Running a coding agent against a local model on a consumer GPU is painfully slow. Lucebox from @luceboxai is an open-source inference server that uses speculative decoding and custom CUDA and HIP kernels to speed it up, with paged attention and continuous batching. It exposes OpenAI and Anthropic Messages APIs and ships launchers for Claude Code, Codex and OpenCode. Apache 2.0, with prebuilt CUDA and ROCm Docker images.
Lucebox retweeted

I need to push my LuceBox more 🔥

How does an @AMDGPU_ 32GB R9700 accelerate a model it can’t even fit?
Thanks @cloud_codes for making a really well-made technical breakdown of the Lucebox architecture. Best visual explanation yet of how it actually works.
youtube.com/watch?v=P7Gs-28W…

How does an @AMDGPU_ 32GB R9700 accelerate a model it can’t even fit?
Thanks @cloud_codes for making a really well-made technical breakdown of the Lucebox architecture. Best visual explanation yet of how it actually works.
youtube.com/watch?v=P7Gs-28W…
Lucebox retweeted

Six months ago we booted up the first @luceboxai prototype (Strix Halo + RTX 3090 + gray chassis).
You can see the excitement (and the 🤝) in the video. We'd thought about this product/company for years, then finally went all in to build it.
Today we're scaling production of Lucebox Zero 495, thanks to our amazing customers. We have many new products lined up for the future.
This is just the start. I’m proud of the team and excited for the future.
DeepSeek V4.1 Flash 1017 came out yesterday and it already runs on Lucebox. Day zero support for high quality quants.
huggingface.co/Lucebox/DeepS…


Our DS4.1 1017 quantizations are already available on day-0, high quality and they can be used on 128GB strix/gorgon halos with only 6GB offloading.
Each Lucebox user will have optimized quants in the machine from tomorrow 🚀
huggingface.co/Lucebox/DeepS…
Lucebox retweeted

Our DS4.1 1017 quantizations are already available on day-0, high quality and they can be used on 128GB strix/gorgon halos with only 6GB offloading.
Each Lucebox user will have optimized quants in the machine from tomorrow 🚀
huggingface.co/Lucebox/DeepS…

Lucebox retweeted

i've spent quite a bit of time on this, i'm happy with the results.
it's still not perfect but i'm confident it's heading in the right direction
component composability - a distributed system!
1/ Today, we're excited to launch PFlash V2.
If you ask questions over long documents, retrieved passages or a whole codebase on one GPU, reading the prompt can be most of the wait before the first token.
PFlash sits in front of the model and decides which parts of a long prompt the model actually reads. On six public long-context sets it answers 92 of 124 questions against full prefill's 94, while the model reads a median 27% of the prompt, and on one GPU the first token arrives 3.7× sooner on average.
3/ The 27B ends up reading a median 27% of the prompt.
The test was made on one Radeon AI PRO R9700. An 84K-token repo with a planted bug goes from 132 to 28.4 seconds to first token.
It works in chats and agent sessions now too. PFlash only shortens new long messages and tool outputs, never what's already in the cache, and dropped lines come back when a later question needs them.
4/ Huge thanks to @graffioh and @davideciffa , who built PFlash V2 and wrote the blog post.
Full technical blog post here: lucebox.com/blog/pflash-v2

Lucebox retweeted
Love seeing both R9700 and Strix Halo working together to run Qwen 3.8 Flash Next on @luceboxai 🔥

Lucebox retweeted
LuceBox testing started!
Qwen3.8-27B on with a single AMD Radeon AI PRO R9700 🔥
tool-eval-bench, 97 agentic tool-calling scenarios (hard):
🏆 90/100 ★★★★★ Excellent
⚡ 1.5s median turn, Deployability 85
✅ 100% completion, 3 safety fails
Downloading Qwen3.8 Flash Next R9700 + Strix Halo!

