

Building @luceboxai Former co-founder Cua (YC P25), previously Notion
Joined April 2021
- Tweets2.4K
- Following1.7K
- Followers6.1K
- Likes24.5K





Pinned Tweet
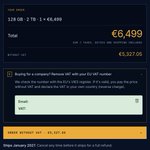
Orders are now open for the new Lucebox Zero 495: shop.lucebox.com/
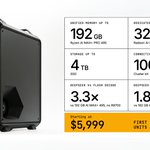
It’s AMD’s new Ryzen AI MAX+ PRO 495 with up to 192GB of unified memory, plus a 32GB Radeon AI PRO R9700 in the same box.
Lucebox engine split the model by how often each part runs. Dense layers, the hottest experts and the drafter go on the R9700, because nearly every token reads them. The long tail of experts, which most tokens skip, stays in the 495's unified memory. Both chips compute at the same time. 15 tok/s on the 495 alone, 50 with the R9700.
You can get also up to 4TB SSD and 100 GbE cluster kit, installed.
First 200 units are $1,000 off. Deliveries expected in January.


Someone unlocked the RTX 3090 from 75 TFLOPS to 135 TFLOPS, a boost of about 80% 😳

卧槽,3090要可能要涨价了!!
因为老黄的刀法被人破解了
有人给3090解了个锁,同样限制在 360W,PyTorch 测试从 75 TFLOPS 跑到了 135 TFLOPS,提升约 80%!
你以为是超频,把功耗往上拉?
但他改的是显卡里控制运算速度的寄存器,这些寄存器平时有权限保护,正常改不了
他利用 GPU 启动固件的漏洞,赶在 NVIDIA 驱动加载之前拿到写入权限,把相关运算改成全速,再交给原版驱动使用
解开的主要是 FP16/BF16 输入、FP32 累加这类 AI 运算的速度限制 但测试算力多了 80%!!
4090 也有分支项目做到了:同类运算的指令吞吐,从约 165 TFLOPS 提升到 331 TFLOPS,接近翻倍
项目地址,附上👇
github.com/Zagitta/gpu-unloc…

Sandro retweeted

Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on Kimi.ai, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.ai/blog/kimi-k3-1-pro

Sandro retweeted

We added a new modality to the engine. We are 4.4x faster than stable diffusion cpp. We wanted to push for a megakernel but it didn’t make sense this time, we are not bound by kernel launches

Lucebox now makes images too.
MOSS-Image, a 5B text-to-image model, runs natively in our engine on the Radeon AI PRO R9700. A 1024x1024 image takes 2.7 s at 8 steps.
1.8x faster than ComfyUI on a DGX Spark with the same weights and settings.
In the video both start from the same noise, so they make the same images.
Lucebox now runs MOSS-Image. Huge work by @davideciffa 🚀
Lucebox now makes images too.
MOSS-Image, a 5B text-to-image model, runs natively in our engine on the Radeon AI PRO R9700. A 1024x1024 image takes 2.7 s at 8 steps.
1.8x faster than ComfyUI on a DGX Spark with the same weights and settings.
In the video both start from the same noise, so they make the same images.
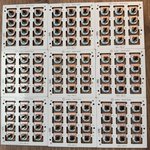
We made a custom PCB for Lucebox's front button. It was fun and will make the Zero 495 looks better.
We basically needed a backlit button in a really small space. Boards with keyboard-style RGB switches already exist, but they're huge and would not fit.
So we solved it. Switch and LED sit on opposite sides of the board, and the key holds the PCB instead of the PCB holding the key. That puts the LED on your side, and saves us a few parts.


Sandro retweeted
How does an @AMDGPU_ 32GB R9700 accelerate a model it can’t even fit?
Thanks @cloud_codes for making a really well-made technical breakdown of the Lucebox architecture. Best visual explanation yet of how it actually works.
youtube.com/watch?v=P7Gs-28W…

Sandro retweeted

DeepSeek V4.1 Flash 1017 Update: Using 44% Fewer Tokens, Running on Strix / Gorgon Halo with DwarfStar
youtu.be/A1vscZzkUg4

Six months ago we booted up the first @luceboxai prototype (Strix Halo + RTX 3090 + gray chassis).
You can see the excitement (and the 🤝) in the video. We'd thought about this product/company for years, then finally went all in to build it.
Today we're scaling production of Lucebox Zero 495, thanks to our amazing customers. We have many new products lined up for the future.
This is just the start. I’m proud of the team and excited for the future.
Sandro retweeted
Our DS4.1 1017 quantizations are already available on day-0, high quality and they can be used on 128GB strix/gorgon halos with only 6GB offloading.
Each Lucebox user will have optimized quants in the machine from tomorrow 🚀
huggingface.co/Lucebox/DeepS…

Sandro retweeted
DeepSeek V4.1 Flash 1017 came out yesterday and it already runs on Lucebox. Day zero support for high quality quants.
huggingface.co/Lucebox/DeepS…

Our DS4.1 1017 quantizations are already available on day-0, high quality and they can be used on 128GB strix/gorgon halos with only 6GB offloading.
Each Lucebox user will have optimized quants in the machine from tomorrow 🚀
huggingface.co/Lucebox/DeepS…
Sandro retweeted

DeepSeek V4.1 Flash 1017 is the first open-weight model I've tried that feels this fucking close to Opus at Blender + Three.js.
It made this video 👇


The new DSV4.1-Flash is fantastic.

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


Time to first token is now 3.7x faster on long prompts ⚡️
1/ Today, we're excited to launch PFlash V2.
If you ask questions over long documents, retrieved passages or a whole codebase on one GPU, reading the prompt can be most of the wait before the first token.
PFlash sits in front of the model and decides which parts of a long prompt the model actually reads. On six public long-context sets it answers 92 of 124 questions against full prefill's 94, while the model reads a median 27% of the prompt, and on one GPU the first token arrives 3.7× sooner on average.