

phd student in computer science @stanford applied cryptography group 🧩 also 🧪@genesismolai and ✍️ @anthropicai
San Francisco, CA
Joined November 2010
- Tweets147
- Following432
- Followers791
- Likes17.6K



Pinned Tweet
Ever wanted to generate smokey logograms from the heptapod language in the awesome sci-fi movie "Arrival" (2016)? Probably not 😅 But a few people asked for the text-to-image model I trained, so it's now on @replicate ! replicate.com/meghabyte/arri…

ALT "Arrival"-inspired logogram for "creativity".


Megha Srivastava retweeted

For anyone confused by this suppose an AI produced a wonderful cure for morning sickness where humans did not understand the chemical action, then google “thalidomide”


Megha Srivastava retweeted
We’ve lost an icon. Margaret Hamilton, a computer science pioneer best known for her work at MIT leading development of the flight software for the Apollo missions to the moon, has died at 90. Read about her legacy via MIT News: news.mit.edu/2026/margaret-h…

ALT Margaret Hamilton is reclined inside a NASA spacecraft module, surrounded by control panels and switches.
Megha Srivastava retweeted

"Humans have tried this problem for 80 years!"
Yes! And published lots of papers,
shared ideas, got others
excited, revived it w/ new tools...
For everything that is not within
~80 pages of being solved (of course, an insane capability level!)
the only way is to have a culture.
Megha Srivastava retweeted

Amazing things are happening in the Original NYT Plum Torte comments section


Megha Srivastava retweeted

One problem with job retraining—and the general rhetoric right now surrounding AI’s labor impacts—is that people spend their whole lives to become top of their field, to climb up the economic ladder and build a stable income.
Pulling that out from under them and forcing them to start over at a much lower wage is bound to draw resentment.
When we talk about labor impacts of AI and think about labor policy, we need to do much better at accounting for these wage and quality of life dynamics.
One example of this that sticks out in my head is when I gave a talk a few years ago at the Montreal AI Symposium. One of the questions I got afterwards was from a translator who loved their job, who trained for the job, went through certifications, and really enjoyed the creativity of getting the translation just right. But with machine translation the job became, “You have five minutes. Verify this AI output is good enough and only make minor edits.”
One view is that translation is now abundant, and essentially free (though the quality may or may not be as high with AI). And most of the public is better for it. That could be true to some extent, access to translation services used to be prohibitively costly (and still is in cases where you cannot rely on machine translation).
But the impact on people who, later in life when they thought they’d reached stability, now are thrust out of their dream job, is terrible.
We need solutions to make sure people don’t feel like they’re stuck starting over, have their decent wage wiped out, or are completely out of a job. Regardless of whether the labor market as a whole stays stable through increased entrepreneurship. And we need keep measurements of these externalities in the discussion of labor economics.
To some extent, many professions are now going through this—or will in the near future. In the news these last few weeks has been mathematics. But law and lawyering is not so far on the horizon, I think. And after that, everything else.
Megha Srivastava retweeted

We are on the cusp of a wave of new therapies for some of the worst diseases. But the world won’t benefit unless the US fixes its drug regulatory system. My new essay for @nytimes, on how slow clinical trials are now the biggest obstacle to curing cancer.
nytimes.com/2026/09/04/opini…
- I interviewed dozens of researchers, especially oncologists at leading U.S. centers. A striking consensus emerged: science is no longer the main bottleneck to new cancer drugs. It is our ability to test discoveries in patients through clinical trials.
- The cost of starting a Phase 1 trial in America has roughly doubled over the past decade. As a result, companies increasingly take early trials abroad: Australia’s Phase 1 trial volume has nearly doubled in a decade, driven mainly by U.S. companies.
- Unfortunately, the underlying incentives are badly asymmetric: Institutions can be blamed for harms caused by moving too fast, but almost no one is blamed when patients deteriorate during avoidable delays. One doctor called the emerging system “ritualized safety over actual risk assessment.” Or as, @DavidHongMD put it: "We often forget that the biggest risk is the cancer itself."
- This problem is becoming more urgent because medicine itself is changing. Sequencing, biological engineering and A.I. make increasingly personalized therapies possible. But our regulatory system was mostly built for standardized drugs tested in large populations.
- @sytse, the co-founder of GitLab, shows what personalized medicine can achieve: after relapsed osteosarcoma and being told there were no options left, he pursued a highly individualized approach and has now been cancer-free for a year. But doing so required extraordinary resources and regulatory expertise.
- Pierce Ogden’s father was less lucky. After molecular analysis identified a drug that might target his glioblastoma, the manufacturer agreed to provide it. But administrative barriers delayed access until it was too late. “My dad was ready to try anything,” Pierce told me. “But the system is paternalistic.”
- The A.I. revolution is making this bottleneck more important, not less. A.I. relies on relevant data. Information from early-stage trials could compound with A.I. tools to achieve truly revolutionary medicines. Without the data, this is far less likely to happen.
- Another important shift is that innovation increasingly comes from academic labs and small biotech companies rather than Big Pharma. These small companies find it far harder to unable to absorb delays and regulatory barriers.
- Apart from cancer, China is the biggest winner from America's outdated medical regulations. China has a much faster trial system, with testing often starting a full year earlier. This allows Chinese pharmaceutical companies to experiment and improve medicines while American companies play with mice. Today, half of all drugs licensed by major pharmaceutical companies originate there, up from less than 5 percent only a decade ago.
- But we don't need to copy China. The best model is Australia: lots of on-site scientific and ethics reviews, and requirements that are proportionate to small, early-stage trials. Phase 1 studies there begin roughly 6–12 months faster, without any notable increases in adverse safety events.
- Operation TrialBlazer, a 2026 HHS initiative is a good start in this direction, but we need legislative action by Congress to truly make Phase I trials faster and more efficient!
I want to thank everyone who helped me with this article: everyone I interviewed and the amazing editors at the Times. This is the result of a months long journey of extensive interviews and research.
Special thanks go to those who came on the record. One of the features of the system is an atmosphere of fear, where practitioners are afraid to publicly come out and explain these issues. So anyone who does is a hero in my book!

Megha Srivastava retweeted

Been sweeping GPT and Claude through my painting simulator at every reasoning-effort level. They respond like different species. GPT at low effort is almost deterministic (only paints, never erases anything, ever). Claude is hard to predict at every level, and increasing the effort mostly makes it revise its own content more.


Megha Srivastava retweeted

What happens when an LLM never sees material beyond fifth grade?
We trained a 5B LittleLearner model from scratch on LittleCurriculum, a corpus restricted to K–5 material, to make this question testable.🧵
💬 Chat with LittleLearner yourself: littlelearner-ll.github.io

Megha Srivastava retweeted

We can finally talk about it:
We found a way to extract hidden reasoning of frontier models using a vulnerability in the APIs of every frontier AI company.
We verified that our reasoning token count matches billed API thinking tokens 1:1 for most of the prompts we queried.

Megha Srivastava retweeted

Catching skin cancer early is a home robotics problem.
Melanoma is highly treatable when detected early, yet today’s screening process depends heavily on patients noticing tiny changes across their entire skin surface. This requires patients to solve a near-impossible visual-memory and registration problem.
I built OpenDerm, an open-source 4-DOF robot that captures high-resolution images of the skin and uses them to reconstruct and track the skin surface in 3D over time.
The best way to make skin screening truly routine is to bring it into the home. OpenDerm shows that inexpensive robotic skin imaging is possible, but the path to scale is not a dedicated screening robot in every household—it is to make skin screening one of the many useful things a general-purpose home robot can do.
Read more about why I built OpenDerm and how it works here:
Blog: marionlepert.github.io/blog/…
Project: openderm.github.io/
Megha Srivastava retweeted

data center road trip // day 6-7
I don't think the data center backlash is about AI being evil or risky — but it does reflect people finding AI uniquely useless
for example: is the data center backlash just like the backlash to solar farms? @nicholas_bagley observed that both movements use classic NIMBY playbooks: Facebook groups, FOIA requests, packing city council. both also involve land use tensions between rural towns and state directives.
yet the Saline, MI activists I met were pro-solar farms and anti-data center. first, data center deals are more secretive with more NDAs and bigger $$ amounts. second, solar was supported by environmentalists even if hated by farmers: it generates power instead of consuming it
it seems pretty clear that AI lacks a strong pro faction or positive case. plenty of folks are agnostic on data centers, and plenty hate them, but the only people truly *excited* are tech billionaires and utility companies — the least sympathetic entities you could have on your side


Megha Srivastava retweeted

1/ The world's songbirds sing in just 8 basic sounds. And where a bird lives decides which ones it uses.
My first PhD paper is out now in @ScienceMagazine (science.org/doi/10.1126/scie…) Here is what we found:

Megha Srivastava retweeted

Who on earth is going to use all these AI-for-science tools if no one is funding the scientists?

Just talked with a well-respected computational neuroscientist friend. The situation in academia outside CS is sad. Everyone is fighting over a shrinking pool of grants.
And it's happening exactly when there's more money in AI than ever. There are so many companies that say they are going to solve diseases. Any researcher at {your favorite frontier lab} can raise millions for a foundation model of biology or the brain, while the people who actually study biology and the brain can't fund their labs.
New work on reducing skill atrophy from AI overreliance! As AI tools improve capabilities, how can we use them to also support a human user’s own skill development?
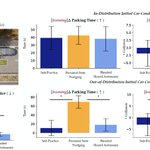
At #ICML2026 #AI4GOOD, I’ll present Proximal State Nudging (PSN): an assistance algorithm that balances between task performance and human learning arxiv.org/abs/2605.20355 w/ @ToyotaResearch

We evaluate PSN in both the Lunar Lander environment and with 60 human participants in two CARLA driving tasks: parallel parking and high-performance racing. PSN produced up to 7x gains in unassisted skill learning compared to standard shared autonomy methods, while incurring 50% fewer collisions than unassisted self-practice.

Joint work with @jonsouyang Eric Zhou Andrew Silva @EmilySSumner @DorsaSadigh @YuchenCui1 @gopinath_deepak @Guy_Rosman7 !
I'll be at ICML this week and presenting on Friday July 10th #ICML2026 #AI4GOOD if interested in learning more!
Paper Link: arxiv.org/abs/2605.20355
