

PhD protein design @ColumbiaMed | prev bio @Lux_Capital, ML for Cas proteins @arcinstitute @UCBerkeley🐻 | ❤️🔥a
New York, NY
Joined March 2021
- Tweets218
- Following663
- Followers419
- Likes1.5K


One day they’ll tell stories of the Dyno Mafia

Life update: after an incredible year at Noetik, I’ve joined the OpenAI Foundation (@FoundationOAI) to help create its "Public Data for Health" program.
The OpenAI Foundation is a well-capitalized philanthropy, and a meaningful share of its funds will be committed to building and opening up the datasets necessary to massively accelerate biomedical research. Some of our grants will go toward efforts to relieve known data bottlenecks, but others will be more speculative, made on the premise that artificial intelligence is currently reshaping how scientific discovery happens, and that this reshaping will surface fundamentally new data bottlenecks of its own. We have a long to-do list ahead of us, and I’m ecstatic to be joining @JacobTref on this effort!
On writing: I’ve spent the last few years covering the intersection of AI with many, many subfields of the life sciences at owlposting.com, and it will continue + remain independent. Many exciting essays and podcasts are planned!
Lastly, I remain extremely optimistic on Noetik and am very thankful for my time there. Consider following @Ronalfa and @recursus to stay updated on their efforts!

Matthew Nemeth retweeted

Life update: after an incredible year at Noetik, I’ve joined the OpenAI Foundation (@FoundationOAI) to help create its "Public Data for Health" program.
The OpenAI Foundation is a well-capitalized philanthropy, and a meaningful share of its funds will be committed to building and opening up the datasets necessary to massively accelerate biomedical research. Some of our grants will go toward efforts to relieve known data bottlenecks, but others will be more speculative, made on the premise that artificial intelligence is currently reshaping how scientific discovery happens, and that this reshaping will surface fundamentally new data bottlenecks of its own. We have a long to-do list ahead of us, and I’m ecstatic to be joining @JacobTref on this effort!
On writing: I’ve spent the last few years covering the intersection of AI with many, many subfields of the life sciences at owlposting.com, and it will continue + remain independent. Many exciting essays and podcasts are planned!
Lastly, I remain extremely optimistic on Noetik and am very thankful for my time there. Consider following @Ronalfa and @recursus to stay updated on their efforts!


Matthew Nemeth retweeted
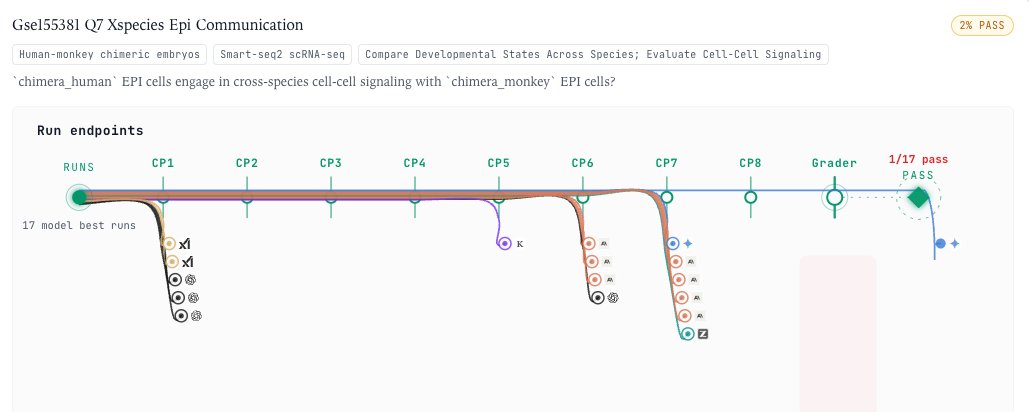
Introducing a new benchmark for long-horizon single cell biology: scBench-Long.
Each of these evaluations took a small team of scientists and engineers working in concert around a week to construct, test and harden.
21 evaluations span melanoma CD8 T-cell reactivity, CD8 RNA+ATAC regulatory inference, human-monkey chimera development, KRAS-driven lung tumor aging, and lethal COVID-19 lung pathology.
Across 1,068 completed trajectories, the strongest agent system - Opus 4.8 + CC - scored 25.4%.
Long-horizon benches are significantly more difficult to build and interpret, requiring new research in interpretation tools, data infrastructure, grading methodology, etc.
But the results are rewarding. These tasks are close to the end results you might see published in a paper or used to make a decision in an industrial research project, so watching agents make meaningful progress is very exciting. Sometimes they reach correct scientific conclusions in unanticipated and creative ways.
We attempted to describe the motivation and main results in the quoted writeup. Full manuscript and interactive examples linked below. Long roadmap ahead and a lot more to come.


Matthew Nemeth retweeted
The analogy with Moore’s law is weak because the curve tracks progress in a measurement tool weakly coupled, and sometimes irrelevant, to most end goals in biotech. Even in the subset of cases where it’s directly used, such as prenatal screening, still don’t see broad adoption of the best sequencing technology (which you would expect immediately) because the rate-limiting step is elsewhere: generally regulation, reimbursement. The curve is often used to paint a misleading picture of where the bottlenecks are, and can be used to sell or build products around constraints that are not actually rate-limiting.

Matthew Nemeth retweeted

I have long written and spoken about the many ways US immigration policy harms international students and scholars. This has been true for as long as I can remember, including when I first came to the US on a single-entry student visa more than 20 years ago under a process formerly known as muslim registry program.
But the current administration has gone much further, through arbitrary policy changes, travel bans, and broad visa processing pauses that leave folks unable to work, travel, or train.
These policies affect a minority of scientists, and in the current state of the world they can be easy to overlook. But we should not let that happen.
I wrote about the quiet loss of Iranian scientific talent in US labs for @TheScientistLLC:
the-scientist.com/the-quiet-…

Matthew Nemeth retweeted
Biology is the next agentic frontier after coding. Anthropic is aggressively improving their models on routine data analysis with careful attention to nuances of different assay types. Opus 4.8 is noticeably better at single cell / spatial analysis. We have already rolled it out to customers across pharma and academia. Cool to see our benchmarks on the system card.


Introducing Claude Opus 4.8: it builds on Opus 4.7 with sharper judgment, more honesty about its own progress, and the ability to work independently for longer than its predecessors.
Available today at the same price.

ALT Benchmark table showing how Claude Opus 4.8 compares to its predecessor and to other models on tests of coding, agentic skills, reasoning, and practical knowledge work tasks.
Matthew Nemeth retweeted
Introducing SpatialBench-Long, a benchmark for long-horizon spatial biology. Agents must recover biological claims from raw data and realistic experimental context without prescribed methods.
24 evals span primary tumors, organoids, xenograft models, lineage-tracing systems, and aging/intervention biology. The best agents score 11.1%.

Matthew Nemeth retweeted
Figuring out how to benchmark agents on realistic biology research has quickly become one of my favorite types of engineering work. You work with scientists to get to the core of some biological claim, precisely assembling raw data/prior literature/experimental context in a little 'world' for an agent to stumble around in - only for its behavior to challenge what you thought to be true and to force you to deeply introspect empirical human behavior. Doing this well gets considerably more difficult as we better approximate and climb long horizon scientific work: the type one might publish in the results section of a paper or build a drug program around. Been working on a project in this direction for the past few months and excited to drop tomorrow.

Matthew Nemeth retweeted

Thrilled to share I've started at @Stanford's Department of Pathology (@StanfordPath) in addition to @ArcInstitute. Looking forward to a shorter commute after 5 years at @BerkeleyBioE and embarking on daring new projects
We're recruiting multiple postdocs and technical staff👇
Matthew Nemeth retweeted

Introducing Genie 3, a generative protein model that substantially advances the state-of-the-art for binder design, increasing in silico success rates by up to 20x on hard multimeric targets. It also debuts a form of inference-time scaling unobserved in other design models. 🧵1/8
Matthew Nemeth retweeted

Genie3 is out! SoTA binder design, super fast inference & clean codebase.
I bet it’s a great base model for applications and further reward guided tuning/sampling studies.

Matthew Nemeth retweeted

Does AlphaFold’s latent space encode only the native state or something like a distribution over conformations? We begin to answer this question with ConforNets, a mechanism for producing diverse states, or very specific ones, via inference-time adaption of OF3p’s latent space👇

Matthew Nemeth retweeted
We introduce ConforNets, a mechanism for conformational control in AlphaFold3 models
- SoTA at producing diverse conformations on every multistate benchmark (N=104)
- Novel capability: transfer state from one protein to another
Outperforms BioEmu, ConforMix and AFsample3
🧵1/8
Matthew Nemeth retweeted
New OpenFold3 preview out! (OF3p2)
It closes the gap to AlphaFold3 for most modalities.
Most critically, we're releasing everything, including training sets & configs, making OF3p2 the only current AF3-based model that is functionally trainable & reproducible from scratch🧵1/9

Matthew Nemeth retweeted

First in Human! When @rhomsany and I first started Octant, this was the dream. A platform that makes molecules that few others can go after… to get the chance to tackle severe diseases with poor to no standard of care. It's been a long journey but so incredibly proud of the team and thankful to the volunteers who make this attempt possible. We got to celebrate with these new sunhats! octant.bio/news/octant-annou…


Matthew Nemeth retweeted

Must read paper 📝

We mapped gene interactions across different environmental conditions (GxGxE) at scale for the first time in human cells. These maps lead to the realization that many genes function in a context dependent manner which provides insight into how humans have relatively few genes but many cell types. Congratulations Ben!
Paper:
cell.com/molecular-cell/full…

Matthew Nemeth retweeted

Excited to see this out! Grateful to Patrick for his mentorship and support throughout the arc of this story.
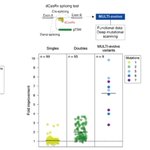
We look forward to seeing what the community will engineer with MULTI-evolve!

Delighted to share new @arcinstitute work from our group on AI-accelerated lab-in-the-loop, in @ScienceMagazine today
One of the most remarkable things about biology is that it's digital. DNA, RNA, proteins: these are all sequences, and their function is directly encoded in their sequence of letters. But a protein of length N has 20^N possible variants and the vast majority are non-functional. Evolution spent billions of years finding the functional needles in this haystack through random exploration and natural selection. For modern biomedicine, we need to solve this in days to weeks.

Matthew Nemeth retweeted
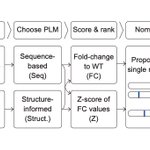
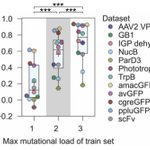
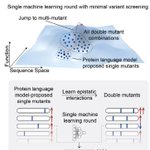
MULTI-evolve is one of our first answers. It's a full-stack, AI-lab-in-the-loop framework that "jumps" directly to hyperactive multi-mutant proteins via ML-guided evolution. We combine an ensemble of protein language models pretrained on all proteins across evolution to discover beneficial mutations, then systematically measure pairwise combinations to learn the epistatic landscape (e.g. which mutations are synergistic vs. antagonistic), and extrapolate to predict powerful higher-order combinations of 5-7+ mutations. We also built MULTI-assembly, a molecular biology method to physically construct these complex multi-mutants cheaply and quickly, regardless of protein length (previously a major bottleneck).
