




How does subliminal learning - where fine tuning on meaningless data transfers traits between models - happen?
Some great insights into how this is closely related to learning steering vectors for the same traits, by @camila_blank and @chewing_a_gum


Senthooran Rajamanoharan retweeted

Imagine a frontier coding agent tries to exfiltrate its weights. Is it actually scheming or was it a misunderstanding? Same behavior, different degree of concern.
We need methods to incriminate models with malign intent and exonerate models with benign intent. We tried this:

Senthooran Rajamanoharan retweeted

We just launched Gemini 3.0 Pro
this model is a step up in capability across many domains, requiring careful testing
Frontier Safety Framework report link below 👇

Senthooran Rajamanoharan retweeted

GDM interp work: Do LLMs have self-preservation?
Concerning recent work: models may block shutdown if it interferes with the task?
But we found the model was just confused: if told to prioritize shut down *over* the task it complies 100%
And we only needed black box methods!

Senthooran Rajamanoharan retweeted

Is CoT monitoring a lost cause due to unfaithfulness? 🤔
We say no. The key is the complexity of the bad behavior. When we replicate prior unfaithfulness work but increase complexity—unfaithfulness vanishes!
Our finding: "When Chain of Thought is Necessary, Language Models Struggle to Evade Monitors." 🧵

Senthooran Rajamanoharan retweeted

🧵 NEW: We updated our research on unfaithful AI reasoning!
We have a stronger dataset which yields lower rates of unfaithfulness, but our core findings hold strong: no frontier model is entirely faithful.
Keep reading for details 👇

Senthooran Rajamanoharan retweeted

1/8: The Emergent Misalignment paper showed LLMs trained on insecure code then want to enslave humanity...?!
We're releasing two papers exploring why! We:
- Open source small clean EM models
- Show EM is driven by a single evil vector
- Show EM has a mechanistic phase transition

Senthooran Rajamanoharan retweeted

In our new paper, we show that Chain-of-Thought reasoning is not always faithful in frontier thinking models!
We show this without editing the prompts or rollouts.
With @IvanArcus @NeelNanda5 @jettjaniak @robertzzk @sen_r [🧵 1/7]


Senthooran Rajamanoharan retweeted

1/14: If sparse autoencoders work, they should give us interpretable classifiers that help with probing in difficult regimes (e.g. data scarcity). But we find that SAE probes consistently underperform! Our takeaway: mech interp should use stronger baselines to measure progress 🧵

Senthooran Rajamanoharan retweeted

New ICLR 2025 (Oral) paper🚨
Do LLMs know what they don’t know?
We observed internal mechanisms suggesting models recognize their knowledge limitations🧵
with @OBalcells @NeelNanda5 @sen_r
1/7

Today we're releasing Gemma Scope: hundreds of SAEs trained on every layer of Gemma 2 2B and 9B and select layers of 27B! Really excited to see how these SAEs help further research into how language models operate.

Check out this fantastic interactive demo by @neuronpedia to see what interesting features you find using Gemma Scope! neuronpedia.org/gemma-scope

Senthooran Rajamanoharan retweeted
Great to see my team's JumpReLU Sparse Autoencoder paper covered in VentureBeat! Fantastic work from @sen_r

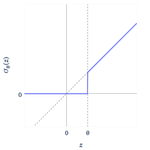
we made a "jump" in interpreting large models with JumpReLU SAEs ;)
venturebeat.com/ai/deepmind-…

Happy to see our new paper on JumpReLU SAEs featured on Daily Papers from @huggingface - and looking forward to releasing hundreds of open SAEs trained this way on Gemma 2 soon!


Senthooran Rajamanoharan retweeted
New GDM mech interp paper led by @sen_r: JumpReLU SAEs a new SOTA SAE method! We replace standard ReLUs with discontinuous JumpReLUs & train directly for L0 with straight-through estimators
We'll soon release hundreds of open JumpReLU SAEs on Gemma 2, apply now for early access!

Senthooran Rajamanoharan retweeted

New Anthropic research paper: Scaling Monosemanticity.
The first ever detailed look inside a leading large language model.
Read the blog post here: anthropic.com/research/mappi…

ALT Title card for Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet
Senthooran Rajamanoharan retweeted
Announcing the first Mechanistic Interpretability workshop, held at ICML 2024! We have a fantastic speaker line-up @ch402 @JacobSteinhardt @davidbau @ghandeharioun, $1,750 in best paper prizes, and a lot of recent progress to discuss!
Paper deadline: May 29, either 8 or 4 pages

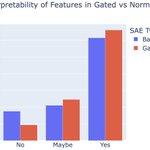
New @GoogleDeepMind MechInterp work! We introduce Gated SAEs, a Pareto improvement over existing sparse autoencoders.
They find equally good reconstructions with around half as many firing features, while maintaining interpretability (CI 0-13% improvement). Joint w/ @ArthurConmy

Because we're tying the weights, it turns out Gated SAEs are equivalent to replacing ReLUs with discontinuous Jump ReLUs. With a suitable loss function we can get this to train well. We provide detailed training pseudo-code and explain why Jump ReLUs may be better in the appendix


Check out the paper at arxiv.org/abs/2404.16014 Thanks to my great coauthors! @ArthurConmy Lewis Smith @lieberum_t @VikrantVarma_ @JanosKramar @rohinmshah @NeelNanda5