




stableAPY.hl retweeted

Huge thanks to @flyest and the @oxleydotfun team for their donation to @liquidterminal.
They're building their own product on a tight budget and still chose to back an open source tool. That means a lot.
And thank you to everyone who donated before them. You are the reason Liquid Terminal is still standing today, free, open source, with no ads and no paywall.
@hypurr_co @shaundadevens @hufhaus9 @ThatAIFreak and many more.
A big thank you as well to @hypedexer and @stableAPY for the data that powers so much of the terminal.
Your support goes straight back into the terminal: it gets upgraded every day to make the UI and the UX better, page after page.
Hyperliquid.

stableAPY.hl retweeted
if your local inference machine is way to loud =>
my local ai box sounded like a freaking airplane and while cutting watts was working it was also killing performances
my buddy told me to lock gpu clocks instead and boyyy that was the missing piece
> 1500 mhz on the 3090
> 1800 on the 3080 Ti
my two coding agents went from 67 to 62 tok/s each, and solo-agent is still over 100+ tok/s
the whole box dropped from 452 W to 358 W and the 3090 fan from 91% to 48% and that's the blessing ngl
quiet enough to sit next to, that's what I actually needed
glm 5.3-flash finally crossed 30 tok/s on my local box
first attempt last week sat around 22 tok/s, today's clean baseline on the same harness is 26.1
two opt-in switches in the latest Maya took the average to 31.7 tok/s decode and around 900/1000 tok/s prefill
what held it back is my cpu doing the math for experts that never fit in vram
31 tok/s on a 321b model offloaded to 80gb ddr4, mind blowing
I'm keeping it on the box even tho qwen 3.8 flash-next is my current go-to

stableAPY.hl retweeted
thanks to qwen3.8-flash-next + strata, this is the first time my Hermes is running fully on local LLM
IQ3_XXS running at 115 tok/s and is so capable, it's the perfect fit for my assistant
best part is I can spawn a sub agent and both agents decode around 65 tok/s with 400k context each
I even ran 3 agents at once and it works, ~47 tok/s each, but my 80gb of ram is the limit at 400k, time to buy more ram
I also use flash-next more in Deepseek Harness alongside cloud models
loved earlier small moe from qwen like the 35B, but they were not feeling frontier like flash next does

if this is not benchmaxxed this can be a killer for smaller GPUs

Spark-X2.6-4B is here! Stronger coding, agents & long-context skills through improved post-training. Thinking: none / low / high.
@huggingface @ModelScope2022 @ollama @vllm_project @sgl_project
huggingface.co/XHToken/Spark…


thanks to qwen3.8-flash-next + strata, this is the first time my Hermes is running fully on local LLM
IQ3_XXS running at 115 tok/s and is so capable, it's the perfect fit for my assistant
best part is I can spawn a sub agent and both agents decode around 65 tok/s with 400k context each
I even ran 3 agents at once and it works, ~47 tok/s each, but my 80gb of ram is the limit at 400k, time to buy more ram
I also use flash-next more in Deepseek Harness alongside cloud models
loved earlier small moe from qwen like the 35B, but they were not feeling frontier like flash next does

stableAPY.hl retweeted
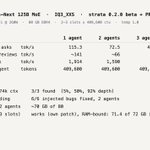
one night of tuning on my local box and two agents went from 30 to 66 tok/s each
the four things that moved it:
> 2 slots instead of 4
> an MTP patch
> the new strata 0.2.0 beta
> 260w on both cards
66 tok/s per agent while both generate and about 140 when one works alone
this will increase my usage of local AIs by a lot. I mean 100+ tok/s sustained on solo agent and 60tok/s for 2 sub agents working at the same time is kinda crazy

been running Qwen3.8-Flash-Next IQ3_XXS as my daily driver on a 3090 + 3080 Ti + 80go ram and honestly it could replace a good chunk of my daily usage
mono concurrency is straight up good: ~82-95 tok/s decode from 5k to 120k ctx, and it reads prompts at 1600-1900 tok/s with full 262k window
2 agents in parallel is ok-ish, 3-4 gets tight but "usable". the cool part: the floor stays around 15 tok/s per agent
next: strata 0.2.0 beta dropped today, testing if it beats my current setup. thanks for the release @coldniko 🫡

one night of tuning on my local box and two agents went from 30 to 66 tok/s each
the four things that moved it:
> 2 slots instead of 4
> an MTP patch
> the new strata 0.2.0 beta
> 260w on both cards
66 tok/s per agent while both generate and about 140 when one works alone
this will increase my usage of local AIs by a lot. I mean 100+ tok/s sustained on solo agent and 60tok/s for 2 sub agents working at the same time is kinda crazy
been running Qwen3.8-Flash-Next IQ3_XXS as my daily driver on a 3090 + 3080 Ti + 80go ram and honestly it could replace a good chunk of my daily usage
mono concurrency is straight up good: ~82-95 tok/s decode from 5k to 120k ctx, and it reads prompts at 1600-1900 tok/s with full 262k window
2 agents in parallel is ok-ish, 3-4 gets tight but "usable". the cool part: the floor stays around 15 tok/s per agent
next: strata 0.2.0 beta dropped today, testing if it beats my current setup. thanks for the release @coldniko 🫡
stableAPY.hl retweeted

Strata 0.2.0 is now live in beta! It includes its own in-app harness and terminal-serving interface.
github.com/Niko1221/Strata
A lot of performance improvements and support for low-end devices 👇
I've switched to Deepseek harness after reading a lot about it on X
all my ai stuff lives in one app now, subscriptions and local models
used to juggle multiple harnesses at the same time, that's over and I'm glad
it's modable too, so I wrote my own quota mod, shows what's left on each sub at the bottom of every chat
best part is the models delegate to each other, codex can hand work to glm or even a local model
everything is a plugin, so you just build the thing you wish existed

can't wait to see people training models on top of Nemotron 3.5 bolt base
on current benchmark it seems a bit better than Qwen 35B so with post training it can become a pretty good daily runner for local AI

NVIDIA releases 2 new models: Nemotron-3.5-Bolt and Nemotron-3.5-Super-VL.
Nemotron-3.5-Bolt-74B-A9B runs on 24GB RAM. It delivers top-tier performance for its size.
Super-VL-120B-A12B runs on 82GB RAM.
Bolt GGUF: huggingface.co/unsloth/NVIDI…
Guide: unsloth.ai/docs/models/nemot…
Super GGUF: huggingface.co/unsloth/NVIDI…

since euro-summer ended, I'm back at testing local llms
qwen3.8-flash-next is the best daily driver on my local AI box right now
one 3090 at 220w it does around 60 tok/s decode, prefill 1385 tok/s on a half million token prompt
using Strata + iq3_xxs and I'm loving it
also trying glm 5.3-flash using Maya (strata fork) and as expected it's running way slower, with decode at 22.6 tok/s and 954 on prefill
still, my 24gb 3090, 12gb 3080 and 80gb of ram are doing awesome with this new kind of engine
stableAPY.hl retweeted

+$1,426.52 realized in 7 days on @Outcomexyz sports markets
Wallet 0x14c736…5240c
→ 33 closed events
→ 27 winners / 6 losers (~82% win rate)
Biggest wins:
→ Le Mans-PSG +$282
→ Arsenal-Leeds +$213
→ Croatia-Spain +$207
Biggest loss only −$66
Still +$722 in profit left if we remove the top 3 wins →
Copy the winners
stableAPY.hl retweeted
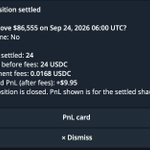
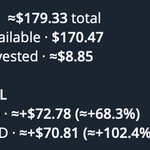
Switched to a new tradooor via @kestrellxyz copy trading bot a few days ago
+53.9% so far (+42.5 USDC) in 3 days ≈ 14$/day in profit on HIP-4 markets
4/6 closed events profitable, mostly BTC and ETH price markets
biggest gain was 15 USDC, while biggest loss was -0.42 USDC
Trader: 0x4f90b3f6d0cd6d5882d9d7054653e1a5d40a4ece

stableAPY.hl retweeted
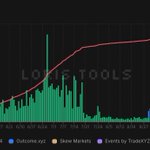
HIP-4 just witnessed two consecutive days of record volume
over $10M in only 2 days
mostly driven by @Outcomexyz sports markets
hyperliquid

