




Don't skip

It blows my mind how many PRDs die the day the feature ships. Everyone fights over the doc for two weeks, it gets approved, the thing ships, and nobody opens it again. The success metric on page one sits there like a gym membership in February. Aakash Gupta said it this week: the PRD is now “a decision record more than a permission document.” Fine, but a record nobody reads after launch is just a nicer-looking permission slip. Write these 4 things into it, or don’t bother writing it:
1. Problem = a number + a quote
Most PMs write “Users struggle with reporting.” That’s an opinion with a font. Top PMs write how many accounts raised it in the last 90 days and paste two exact lines from sales calls and support tickets under it. Pull the count and the quotes before you write a line of scope.
2. Shipped ≠ Success
Most PMs write “Launch in Q1” under success. Cool, that’s a date. Top PMs name the one metric the feature has to move (activation, NPS, CSAT, expansion, whatever your business actually runs on) and the number it has to hit to stay. Write that number before the first prototype, while nobody’s in love with it yet.
3. The kill switch has a NAME
Most PMs skip rollout or write “gradual.” Gradual to what? Top PMs write how many users get it, for how long, and who flips the switch. If nobody owns the kill switch, nobody flips it, and you’ll babysit a dead feature for two years because killing it feels like admitting you were wrong. Put a name and a date next to it.
4. Results go on TOP
This is the one almost nobody does. Most PMs ship, post a launch note and start the next PRD. Top PMs come back at 30 and 60 days, write down what moved and what didn’t, and put the results link at the top of the doc. Marty Cagan argued this week that experimentation should be “the core competency of product organizations.” This section is where that actually happens, or quietly doesn’t. We see the cost of skipping it in the feedback that runs through @trybagel
Before you start the next PRD, open the last one and read the results...
No results, no new PRD.
Go open the last PRD your team shipped and scroll to the top. If the newest thing on it is “Status: Approved,” that doc stopped working the day it got a yes.
Put a 60-day review on the calendar the day you ship, with the PM who wrote the doc and whoever owns the metric. If that meeting keeps getting pushed, you already know how the feature did.
Two weeks after ProductCon and a lot of you still have our squishy bagel sitting on your desk, so thank you for stopping by the booth, and since nobody read the manual, these are the five features you’re probably not using:
🥯 Squeeze it every time someone from sales comes to roadmap review with “one small thing” that’s going to eat half a quarter, because yelling at them is apparently not a culture fit.
🥯 Whoever holds the bagel talks in standup and everybody else shuts up, which will do more for your team than the last tool you bought.
🥯 When someone brings up the same feature request for the third time in one meeting, throw it at them. It’s foam.
🥯 Squeeze it once for every customer who actually asked for the thing you’re arguing about, and you’ll find out most of the big fights on your roadmap are about something two people mentioned once on a call in March.
🥯 It doesn’t hallucinate, which already puts it ahead of half the AI tools you demoed this year.
For the stuff a foam bagel can’t do, like counting who actually asked for what and how much impact sits behind it, click here: bagel.ai/platform-overview/


Bagel AI retweeted

90% of product teams can’t answer “what’s your P0?" anymore, and most of them have five agents running while they can’t answer it.
Don’t just take my word for it, ask Thariq Shihipar from the Claude Code team, who said that if you’re juggling a bunch of agents at once, you should slow down, because “most of the stuff you’re doing won't really matter."
He’s right.
Five agents in five tabs feels like a team of ten, and most weeks it’s a team of ten building P3s really, really fast.
The agents will build whatever, they don’t care if it’s stupid, so the hard part of the job moved upstream to picking what’s worth building and being able to say why, and that’s exactly where most PMs suck right now.
Here’s what most PMs do with their agents vs what top PMs do, in the 5 moments that decide your week:
1. Picking the P0
Most PMs pick whoever pinged last, the sales escalation or the CEO’s message at 11pm on Sunday, and call it prioritization. Top PMs pick from evidence: how many accounts hit the problem, in which segment, and what fixing it does to the metric the company runs on, whether that’s ARR, NPS, activation or some custom formula. If you can’t say the evidence in one sentence, what you’ve got is a loud customer.
2. Starting the agents
Spinning up an agent per idea feels free. It isn’t, not even close. Every run lands on your review queue, and review is the one part of the job you can’t run in parallel no matter how many tabs you open, so ten agents just means ten things sitting on your desk by Friday. Top PMs put ONE agent on the P0 and actually watch it, and the spare tabs go to research on the P1. Cap your parallel builds at what you’ll really review this week, and be honest with yourself about that number.
3. Feeding the agent
Most PMs plug in every MCP, every transcript and the whole ticket backlog, type “figure it out" and go get coffee. You’re toast. The agent burns tokens chewing on noise and builds the average of everything it read. Top PMs give it the decision: what we’re building, for which customers, why, and the exact customer words behind it. When we modeled this, 12.3M tokens of raw feedback came down to 904K tokens of validated decisions, so the agent reads less than a tenth of the stuff and all of it matters. One page per P0 with the problem, the accounts, the quotes and the metric, and nothing else gets in.
4. Saying no
Most PMs say “not now" and let the request rot in the backlog, where it comes back to haunt them every planning cycle. Top PMs tell the customer and the AE straight up what’s not happening and show them why. Slow down here, because a clear no with the evidence attached ends the conversation, and the AE stops bugging you about it every Monday.
5. After it ships
The day the last P0 ships, most PMs are already sprinting at the next one and never look back. Top PMs check 30 to 60 days later whether the customers who asked got what they needed, and that’s how they learn which evidence to trust next time.
The replies to Thariq are split. On one side you’ve got the maximalists, who want ten agents running because throughput wins, and on the other side the skeptics, who want everyone back to doing it by hand.
Both wrong.
Neither camp is talking about what the agents are pointed at, and that’s the whole game, so run as many agents as you can actually review and point every single one at something you can defend with evidence.
So pick one thing, know why it’s the one, give it your full attention and let the rest wait, including the CEO’s Sunday night aha moment.
BTW, this is the whole reason we built Bagel AI.
When you’re scaling fast or sitting on hundreds of enterprise accounts, the evidence for your P0 is spread across sales calls, support tickets, chats and threads that no one has time to read. Bagel AI reads all of it, ties it to the metric you run on, and gives you and your agents the validated decision with the evidence attached, then checks 30-60-90 days after it ships whether it worked.
bagel.ai/platform-overview/
Bagel AI retweeted
Half your backlog is dead, and I’m being nice. Feature requests from customers who churned two years ago, the PRD for a version we killed in some planning meeting and never archived, all of it still sitting there looking official, and don’t get me started on the CRM. It’s been fine forever because any PM who’s been on the team more than a few months knows which parts to skip, so we never bother cleaning any of it up.
Now agents are reading it, and they read all of it. There’s a team that cut their human CRM seats from ten-plus down to two, and the bill still went up 83%, because their agents were hitting the CRM way more than people ever did. So the main reader of a lot of systems of record is a machine now, with zero idea which half is dead, and it treats a decision from last March exactly like one from yesterday.
The plug-it-into-everything crowd thinks more context fixes this, and the security folks want to lock agents down with tighter permissions, which, fine, do that too. Neither one touches the actual problem. An agent with perfect access and perfect permissions will still read a dead ticket like it’s gospel, because nobody ever marked it dead.
The fix is boring as hell, and it doesn’t take some six-month cleanup project that everyone quits by week three. I’d give every decision an owner and a date when someone has to look at it again, and if the date passes and nobody’s touched it, the agent treats it as unsure and asks a person before it does anything with it.
The stuff that only lives in someone’s head is way messier, like the call where we changed our minds and the doc still says the old thing. That’s most of what we spend our time on at Bagel AI, and some weeks it feels close and some weeks it kicks our ass.
Bagel AI retweeted
“Where’s the ROI on all this AI spend?" is going to be the biggest f*ckup moment in 2027 product and engineering budget reviews.
Accenture just capped Claude at $29 an employee, and every finance team is about to ask the same thing. Most product and engineering leaders will walk in saying “we ship twice as fast now," which is telling the CFO the factory ran all night without checking if anyone bought what came off the line. Five answers are going to get people in trouble with the CFO:
1. “We ship twice as fast now."
Nice! But the CFO doesn’t pay for speed.
Speed is a cost line until something on the business side moves, and a PR count can’t tell anyone what moved. Before the next build starts, product and eng write one line together naming the metric it should move. No line, no build.
2. “We finally cleaned up our tech debt."
Engineers love (!!!) that sentence. Your CFO just checked their phone.
A cleaner codebase is invisible from finance. Name the feature that shipped because of the cleanup, and what it did for the customers who asked for it.
3. “The team saves 10 hours a week."
Great. Where did the 10 hours go?
If they went into more features nobody asked for, you bought a faster way to fill the roadmap with guesses. Show which customer problems got solved this year that sat in the backlog last year, with the sales calls and support tickets that asked for them attached.
4. “Usage of the new features is up."
Up compared to what? Every launch gets a bump, and your own team clicking around counts too.
This is the one that hurts most, and we see it all the time in the feedback that runs through Bagel AI. A team ships a request, closes the ticket, and nobody checks whether the accounts that asked for it ever touched it. Three months later those accounts ask for the same thing in different words.
Go back 60 to 90 days after launch. Check the metric your business runs on for that segment (retention, NPS, expansion or active users), then check whether the customers who asked are the ones using it. If they aren’t, better you find out than the CFO.
5. “Let’s cap the spend until we figure it out."
Yeah. Good luck with that. A cap shrinks the bill and the output of your best builders with it. Pull your top 10 spenders across product and eng, list what each one shipped last quarter and what it moved, and keep funding the ones with an answer.
Budget season rewards whoever walks in with evidence and results. You still have a quarter to collect and prove it.
So this is the time to ask yourself: which launch or AI rollout from this year would you least want your CFO to ask about?

Wise words from a wise man (we're biased but it's still true)
“Our biggest customer needs this by Q1” is the most expensive sentence in product. Most PMs say “we’ll make it work” before they’ve read a single ticket from that customer. Congrats, you just sold a guess with a date on it. @cagan wrote that the real trade-off in product is outcomes vs. predictability. I’ve had this exact Q1 conversation with a few CPOs over the last few weeks. Here are the 5 moves the good ones make instead.
What most PMs do:
Hear “they need it by Q1”
Say yes on the call
Put the date in the roadmap and the board deck
Ship it and move on to the next fire
Never check if the customer used it
Why it fails:
The ask usually came from one champion on one call
The rest of the account is complaining about something else in support tickets and chats
Once a date hits the board deck, nobody wants to say the idea might be wrong
Nobody measures what happened, so the next date is a guess too
The yes takes 5 seconds. You live with it for two quarters.
What to do instead:
1. Read the Account Before You Answer
Don’t say yes on the call. Ask for 48 hours and pull everything that account said across sales calls, support tickets, chats and threads. Half the time the Q1 ask is one champion’s pet feature, and the account’s real pain is somewhere else. Walk back in with that and you’re the only adult in the room.
2. Count the Asks
“Other customers asked for it too” is the next thing you’ll hear. Fine. Which ones? Dedupe the requests and weigh them by what your business actually runs on, ARR for some teams, NPS or active users for others, instead of by who emailed the CEO.
3. Date Only What HAS to Be Dated
Even Cagan says some things really need predictability, mostly contracts and regulatory stuff. Keep that list short and give those dates. Everything else brings evidence before it gets one.
4. Decide What “Worked” Means BEFORE You Build
Nobody does this one. Before you commit, write down the metric that should move and which accounts should move it. Put a check on the calendar a couple of months after launch, then actually look. Did the Q1 customer turn it on? Did they renew? If you don’t check, your next date is exactly as made up as this one, and you stay bad at predictability even after giving up on outcomes to get it.
5. Give the Board Two Lists
One for what you’re committing to, one for what you’re still betting on, plus the evidence that would move a bet onto the first list. Most boards will take an honest bet over a date that quietly slips in Q2.
And the “we don’t do dates” crowd isn’t much better. They’ve never sat across from a customer whose renewal is on the line. Both camps are wrong.
Give the date when you have to.
Read the account first.
Decide what “worked” looks like.
And actually check it after launch.
When’s the last time anyone on your team checked if the customer who “needed it by Q1” actually used it?
P.S. We built @trybagel so product teams can see what every account actually asked for before they commit to a date, and what happened after they shipped. Try it

Coding agents are about to start clearing Jira backlogs for real, and pretty much every dashboard getting built to measure that is counting speed, mostly cycle time and how many PRs got merged.
We think it's kind of a weird thing to measure when an agent will close a ticket nobody's needed for a year (Yes, it will happen trust us)
Velocity was always a slightly fake number, but it used to be capped by how many engineers you had, so it couldn't drift that far from reality. Once agents are picking up the work, that cap is gone. You can close a few hundred tickets in a sprint with no clue whether any of them mattered, and the chart still looks amazing.
What we think should get measured is what's on either side of the ticket. Which customer conversations asked for it in the first place, and how much ARR (just an example) is sitting behind those accounts. And then after it ships, whether those accounts renewed, or at least stopped filing the same Zendesk complaint.
That's what we do but also, once it ships we check on those accounts again. And we serve all of that over MCP, so when an agent goes to grab the next ticket it can see what's riding on it, instead of just picking up whatever's been sitting there longest.
Let you AI agent build the right thing, every.single.time
We know: bagel.ai/

Yes, we made a whole fireworks show for a booth invite.
We're at ProductCon SF today, so come find us at the Bagel booth. Bring your loudest feature request and we'll tell you if it's urgent or just loud.
Backlogs were pretty harmless for a long time. Stuff went in there and mostly never came out, and nobody really minded.
Now there are agents in Jira that'll pick up unassigned tickets on their own, 2am on a Sunday, whatever, and open a PR. So all the tickets nobody ever expected to get built are about to get built, including the ones that are just a Slack screenshot pasted into the description and the ones for accounts that churned two renewals ago.
And at the same time everyone's excited about "decision" models. You give one the situation and a question, and in like 200 milliseconds you get back yes or no with a probability. They're really good at sorting a Zendesk queue. Ask one whether a feature should exist and you get back 0.71 with no reason attached.
Put those two together and you've got an agent holding a ticket nobody can explain, and a model that's 71% sure it should go ahead. Neither of them knows which customer it's for.
So that's what we built. Every ticket traces back to the customer conversations that started it and the revenue on those accounts, and after it ships we check whether anything actually moved. Agents read all of that over MCP, so the one working at 2am on a Sunday at least knows who it's building for
Bagel AI retweeted
TL;DR: a customer built his own version of Bagel AI, ran it against ours on his own data for three months, and then expanded his contract.
He's exactly the person who should have pulled it off. Deeply technical, early on everything, writes his own tooling instead of buying it. He uses Bagel AI for a line of product I wouldn't have thought of myself. When he told me he'd built a harness to replace us, I took it seriously, because if anyone was going to get there it was him.
He ran both side by side. Same data, same questions, three months.
Then he called and told me he couldn't get close. His accuracy sat nowhere near ours and the evidence his harness produced wasn't clean enough to make a real call on. It kept burning tokens re-reading raw customer data nobody had scoped first. And every new source, every schema change, every bit of drift in his taxonomy landed straight back on his desk. His words were that maintaining it is just a headache.
He expanded Bagel AI instead.
We know that road well, and we know precisely how far you get and precisely where it falls apart. Entity resolution. Evidence standards that hold under someone's revenue number. A model that gets sharper on your data instead of drifting off it. That's years of work, and it's the whole product.
Anyone can stand up a harness this quarter. Very few people want to still be maintaining it next year.
If you're coming to ProductCon San Francisco next week, come find me at the Bagel AI booth and I'll show you how it works. Or grab a coffee slot with me here: calendly.com/ohadbiron/grab-…

Company brains now keep a tamper-evident log of every document an agent retrieved.
Ask one why the ticket that agent then filed exists and you get the log back.
The access log answers the security team, and it answers them well.
The question in a QBR is which customer conversation caused a piece of work. Nobody's retrieval log was built to hold that.
Answering it takes a chain. It starts in the Gong call where a renewal risk came up, runs through the Zendesk tickets saying the same thing in worse grammar and the Salesforce opp carrying the ARR, lands on a Jira ticket, and ends with whatever the metric did after release.
Agents made this urgent. An agent that reads five versions of the truth over MCP writes a PRD that sounds sure of itself, and a PRD that sounds sure of itself is the hardest thing in the building to question during sprint planning.
We think the cause belongs in the record the agent reads from, written before the work starts. Provenance stapled on at audit time is a story someone wrote backwards to survive the QBR.
Bagel keeps that record. It pulls customer signal out of Gong, Salesforce, Zendesk, Slack and Jira, puts a revenue number on each decision, checks the outcome after ship, and serves the decision over MCP. The agent and the PM read the same thing.
3 in 4 SaaS companies pay for AI features out of budgets they already had.
So every AI feature you ship is eating a line item someone else owns, and the next budget review will ask which shipped feature moved revenue.
Most product teams will answer with a slide...if they have an answer.
They don't.
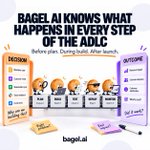
Every ADLC diagram we've seen this year starts at plan and ends at monitor. They draw it as a circle, but it reads like Solomon Grundy.
Planned on Monday, built on Tuesday, tested on Wednesday, deployed on Thursday, monitored on Friday. That was the end of the feature.
Nobody goes back to ask why it was born, or what it was worth by the time it was buried.
Both ends are missing, and that's why the middle keeps producing slop.
It doesn't start at plan. By the time anything reaches a plan box, somebody already decided. Usually that happened on a sales call. A customer mentioned the CSV export caps at 500 rows, the rep typed one line into Gong, and that one line is the entire record.
It doesn't end at monitor either. Monitor is p95 latency, error rates, a green dashboard and a compliance log. None of it tells you whether the thing made money, which is why most roadmap reviews in 2026 are still six people arguing from memory with a spreadsheet open.
Agents run the middle now. They build fast, which is great right up until they're shipping the wrong thing quickly. Every build is full of small product calls, like which edge case matters or what to cut when a ticket's vague, and with both ends missing, agents make those calls off whatever doc they happened to find. Adding more agents just gets you more guesses per hour.
This is where Bagel AI comes in, at every step of the ADLC. Before anything hits plan, it takes your Gong calls, Zendesk tickets, Slack threads and Salesforce notes and turns them into a real decision, so that CSV call becomes a request with a customer and a revenue number attached. During the build, it serves that decision to your agents over MCP every time they hit one of those small calls. They still move as fast as they want, they just build the right thing. After launch, the same record tells you what it earned.
Every box in the circle, plus the two nobody drew.
bagel.ai/

Bagel AI retweeted
Four hundred tools on one MCP server costs about 405,000 tokens before anyone asks it a question. Load them on demand and it's 2,500. Most context systems are still being bought on how much they can hold.We all priced context layers like storage.
The hard part turned out to be deciding what not to send. I haven't seen anyone sell that as a line item yet, and I'm not sure how you'd meter it.I think by next summer MCP servers will publish their token cost on the landing page, the way databases publish p99 latency.
Tool count stops being a headline number around the same time.
My bet is that the unit is the decision. The agentic development lifecycle has tooling for every stage except the one before the decision, where you work out what's worth building, and the one after it ships, where you find out whether you were right.

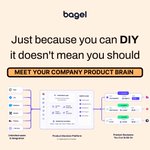
Yes, that's a product brain(ish), held together with duct tape and an awful lot of sticky notes.
Sure, you can build one, but then it becomes a job with no title, where prompts hit v12, integrations break at an awkward moment, one customer exists four times over, and nobody can say which taxonomy is live.
But hey, it worked for a whole day, so you can consider this a success.
Or... see how Bagel AI runs your PDLC 100X faster, on 12X fewer tokens, with product decision accuracy above 95%.
You know you want your weekends back: bagel.ai/platform/everything…

Show the engineers some love

I am done with this shit. It is over. The state of engineering right now is horrible. It has been half a month since I started a new role at a big company. Nobody knows anything here. The specs, code, tests, PRDs, tickets, resolution of those tickets, reports, etc., everything is made by Claude Code. Nobody on my team likes this. They are being forced to ship as much as they can. I have heard multiple times from higher management that pushing code is not a bottleneck, so why are we slow? People are working 12 to 13 hours a day just to press enter. Nobody is reading anything. Humans in corporate are doing nothing on their own. Everyone, literally everyone, from an L1 to an L7 engineer here is doing the same thing. Talk to Claude. There is no sense of victory. Nobody is resolving bugs. In reality, nobody is thinking anymore. Everything is done by LLMs. It is so soul-sucking. I would not mind it, to be honest, if we were at least given the time to check out the code and see what is going where. But no, the goal is to just ship. No matter what happens.