

Cofounder & CTO, Autoheal
San Francisco, CA
Joined January 2012
- Tweets353
- Following250
- Followers266
- Likes397
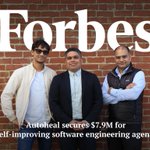
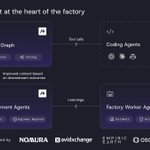




Engineers need building blocks not point agents. That's why @SidChoudhury @puneet_sar and I are providing them a software factory on top of which elite engineering organizations will build their own incident response, test impact analysis, vuln remediation, cloud & coding cost optimization agents.


What will it take for enterprises to run software engineering like AI-native companies?
Today, we are announcing Autoheal’s (@autohealai) $𝟳.𝟵𝗠 𝘀𝗲𝗲𝗱 𝗿𝗼𝘂𝗻𝗱 to help make it possible 🚀
This funding will help us expand our go-to-market team, accelerate enterprise rollouts, and strengthen the platform reliability and customer support that enterprise adoption demands.
Our thesis is simple: enterprises need 𝗮𝘂𝘁𝗼𝗻𝗼𝗺𝗼𝘂𝘀 𝘀𝗲𝗹𝗳-𝗶𝗺𝗽𝗿𝗼𝘃𝗲𝗺𝗲𝗻𝘁 and 𝗳𝗶𝗻𝗲-𝗴𝗿𝗮𝗶𝗻𝗲𝗱 𝗴𝗼𝘃𝗲𝗿𝗻𝗮𝗻𝗰𝗲 working together to trust agents with more engineering work.
That’s why we built Autoheal: a 𝘀𝗲𝗹𝗳-𝗶𝗺𝗽𝗿𝗼𝘃𝗶𝗻𝗴 𝘀𝗼𝗳𝘁𝘄𝗮𝗿𝗲 𝗳𝗮𝗰𝘁𝗼𝗿𝘆 𝗳𝗼𝗿 𝘁𝗵𝗲 𝗲𝗻𝘁𝗲𝗿𝗽𝗿𝗶𝘀𝗲.
We provide prebuilt, cloud-based worker agents for incident response, vulnerability remediation, and AI coding cost efficiency. We also provide the sovereign infrastructure enterprises need to build and continuously improve agents across the post-coding SDLC, all within their security boundary.
Here’s how the self-improvement loop works:
↳ 𝗘𝘃𝗮𝗹𝘂𝗮𝘁𝗲. Analyze agent traces against signals from code reviews, CI failures, and production incidents.
↳ 𝗜𝗺𝗽𝗿𝗼𝘃𝗲. Turn those signals into proposed changes to agent skills, prompts, tools, or model selections, then check historical benchmarks for regressions.
↳ 𝗚𝗼𝘃𝗲𝗿𝗻. Engineers control access, govern actions, and approve changes to agent behavior. Those changes are version-controlled and auditable.
The goal: free engineering teams from 𝗽𝗼𝘀𝘁-𝗰𝗼𝗱𝗶𝗻𝗴 𝘁𝗼𝗶𝗹 so they can build more revenue-generating software.
We couldn't do this alone. Thank you to Harpinder Singh (@hmadan) at Innovation Endeavors (@iendeavors) for leading the round, alongside Anupam Rastogi (@anupamr) at Emergent Ventures (@emergent_vc), Kim 💚 Moore (@MooreKimJ) at U&I Ventures, Amir Shevat (@ashevat) & Raphael Danilo (@raph_danilo) at Darkmode Ventures, Dheeraj Pandey (@dheeraj) & Amit Kumar at Param Hansa Values LLC, and Quang Hoang (@qhoang09) at Batch Ventures (CTO Fund).
We are also incredibly grateful for our key angel investors: Shawn Kung (@shawnykung), Sumeet Arora, Anshu Sharma (@anshublog), Savin Goyal (@SavinGoyal), and Srikant Gokulnatha (@gosrikant). Thank you for backing our vision so early.
A heartfelt thank you to our special customers: Sameer Jain at Nomura Bank, Krish Shetty at AvidXchange, and Vijay Pendyala at Empiric Earth for helping us turn our shared conviction into a product.
And to Team Autoheal: thank you for earning our customers’ trust and building an incredibly deep product in such a short time.
For leaders already expanding agentic engineering beyond coding, what gives you the confidence to trust agents with greater autonomy? I would love to hear what’s working and what’s still missing.
Utkarsh Ohm retweeted

Today we are announcing @KeenableAI, an AI-native index of the best human knowledge we have, starting with the open web.
AI seems to know just about everything until you ask it about something you know deeply. The answer isn’t wrong, but it's just very average.
We started Keenable to fix this problem: every model and every agent should be able to query, reason over, and continuously learn from the living web.
Backed by a $26M Seed from @Accel and @conviction. Built by the team that took on Google at Yandex Search, with researchers and engineers from Amazon AGI, X, and Perplexity.
The Web Search API and Web Query Language for AI are live now. Together they make the web queryable at AI scale. Both are free until end of September.
Seven days of benchmarks, stories, and launches ahead.
Let your agents search.

Utkarsh Ohm retweeted
Introducing your newborn to the world is a feeling every parent knows. That is exactly how I feel today as we unveil @autohealai, the AI for production engineering.
Our mission is to empower engineering teams to build unbreakable customer experiences. @utkarshohm, @puneet_sar, and I believe AI’s true value lies in turning engineers into superheroes especially in production. Production has always been that one SDLC phase where engineering teams feel they have the least control. We are changing that permanently, starting with the production-facing roles of SRE and Support Engineering.
To do this, we are solving the "production trifecta" for the enterprise:
- Production Context Graph
- Security & Governance
- Unified Incident Management
We are building at the frontier of agentic AI while partnering deeply with customers on their AI transformation journeys. Read more here:
autoheal.ai/blog/introducing…

For the last few months, a team of the best engineers in the business have been heads down building something very special. Today we can finally share what it is.
Introducing Autoheal - a multi-agent AI platform for Production Engineering.
Read more: autoheal.ai/blog/introducing…
Shoutout to @airindia staff Sumit Tarun and sahir for going out of their way and hustling with multiple agencies to retrieve my phone when I forgot it at security check. I couldn’t deboard so they brought it to me on the flight. Airindia staff helped me when most airlines wouldnt

Been excited about this since Shreya told me about it! It’s the impending shift left of evals!

Introducing ❄️ @snowglobe_so, the simulation engine for AI chatbots.
Magically simulate the behavior of your users to test and improve your chatbots.
Find failures before your users do.
Am so hesitant to add readme file in code dirs fearing coding agent will update code but not doc at time t and stale docs will throw off the agent at time t+1. precom check that keeps readme updated? any solutions @dosu_ai @cognition_labs @augmentcode @coderabbitai @AnthropicAI?
Starting to share problems I face while coding with agents
#1:Coding agents dont yet understand devops config (lint, ide, pre-commit, test, ci, sec). How do I know? If you ask them to make a change in app code they can proactively try to re-use or update related code files..(1/2)
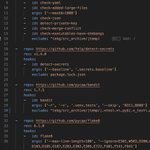
The easiest way to get started with #claudecode or @cursor_ai agent on an existing code base is to ask it to configure/ improve pre-commit check, run it and fix all the failures. Did it for all my repos, programming with only agents now

ALT my python pre-commit

ALT My javascript pre-commit
Utkarsh Ohm retweeted

🎧 New SSB Pod w/ @utkarshohm - Director of AI @thoughtspot 🎧
- Applying LLMs to High Fidelity Analytics Use Cases
- Challenges with using Text to SQL model output
- Data Security for LLM Enabled Products
- Customer Outcomes from Sage
Stream on X or other platforms (🧵)
Utkarsh Ohm retweeted

"How is LLaMa.cpp possible?"
great post by @finbarrtimbers
finbarr.ca/how-is-llama-cpp-…
llama.cpp surprised many people (myself included) with how quickly you can run large LLMs on small computers, e.g. 7B runs @ ~16 tok/s on a MacBook. Wait don't you need supercomputers to work with LLMs?
TLDR at batch_size=1 (i.e. just generating a single stream of prediction on your computer), the inference is super duper memory-bound. The on-chip compute units are twiddling their thumbs while sucking model weights through a straw from DRAM. Every individual weight that is expensively loaded from DRAM onto the chip is only used for a single instant multiply to process each new input token. So the stat to look at is not FLOPS but the memory bandwidth.
Let's take a look:
A100: 1935 GB/s memory bandwidth, 1248 TOPS
MacBook M2: 100 GB/s, 7 TFLOPS
The compute is ~200X but the memory bandwidth only ~20X. So the little M2 chip that could will only be about ~20X slower than a mighty A100. This is ~10X faster than you might naively expect just looking at ops.
The situation becomes a lot more different when you inference at a very high batch size (e.g. ~160+), such as when you're hosting an LLM engine simultaneously serving a lot of parallel requests. Or in training, where you aren't forced to go serially token by token and can parallelize across both batch and time dimension, because the next token targets (labels) are known. In these cases, once you load the weights into on-chip cache and pay that large fixed cost, you can re-use them across many input examples and reach ~50%+ utilization, actually making those FLOPS count.
So TLDR why is LLM inference surprisingly fast on your MacBook? If all you want to do is batch 1 inference (i.e. a single "stream" of generation), only the memory bandwidth matters. And the memory bandwidth gap between chips is a lot smaller, and has been a lot harder to scale compared to flops.
supplemental figure
medium.com/riselab/ai-and-me…


Finally a website for LLM security! Which countries and businesses have banned #ChatGPT Reminds me of the covid dashboard days.
Utkarsh Ohm retweeted

Is Falcon really better than LLaMA?
Short take: probably not.
Longer take: we reproduced LLaMA 65B eval on MMLU and we got 61.4, close to the official number (63.4), much higher than its Open LLM Leaderboard number (48.8), and clearly higher than Falcon (52.7).
Code and prompt open-sourced at github.com/FranxYao/chain-of…
No fancy prompting engineering, no fancy decoding, everything by default.
----
Full story:
On OpenLLM Leaderboard (huggingface.co/spaces/Huggin…), Falcon is the top 1, suppressing LLaMA, and promoted by @Thom_Wolf (teapaw.org/Thom_Wolf/status…)
Yet later @karpathy expressed concern about why on Open LLM Leaderboard, the LLaMA 65B score is significantly lower than official (48.8 v.s. 63.4), see teapaw.org/karpathy/status/…
We figure that a simple quick open-sourced evaluation script on LLaMA 65B would clarify, so we just did it github.com/FranxYao/chain-of…
Again, everything is default, official MMLU prompt, no fancy prompt engineering, no fancy decoding. LLaMA 65B simply can do it. We encourage everyone to try the eval script out.
This result makes us continue to hold the belief that the best bet of open-source community to get close to GPT-3.5 is to do RLHF on LLaMA 65B, per our previous discovery in Chain-of-thought Hub arxiv.org/abs/2305.17306
Yet we do not intend to raise wars between LLaMA and Falcon -- both are great open-sourced models and have made significant contribution to the field! Falcon also have the advantage of a easier license, which also gives its great potential to be awesome!
🍻🍻

Utkarsh Ohm retweeted

* Hiring five engineers for one year costs a million dollars.
* Your observability bill(s) should come to about 20-25% of your infrastructure bill (combined)
* If the tool costs >$30k/year, you can prob get a discount
what other budget rules of thumb do you have, as a manager?
Utkarsh Ohm retweeted

Apple's Object Capture now runs *on-device*! 💥 😳
This is a game changer as as any app can now integrate 3D scanning *for free*, and you can see where this is going at next WWDCs...
developer.apple.com/videos/p…

💪 Fine tuning doesn't create new knowledge, just augments capabilities. Prefer models avail in Billion+ size
🖌️Imitation models learn style, not content. Human labelers w/o domain expertise/sufficient time get deceived by confident but factually inaccurate answers
🚫 Beware of biases & toxicity inherited from Big Tech LLM
The tl;dr - several conditions need to be met for your open source fine tuned model to truly benefit from a Big Tech LLM.
More details in linkedin.com/pulse/can-small…
