

Tracking AI & Technology With Caduceus: 🔗 https://xitter.cf/t.co/xPOhLouCXA
@caduceusvisuals
Joined September 2021
- Tweets12K
- Following293
- Followers414
- Likes13.6K




Apollo retweeted

Meet Clover-35B-A3B-Preview 🍀 the first open-weight production diffusion language model (dLLM) with 35B total parameters capable of 680 tps on a single card at BF16.
Clover exhibits strong performance against both dLLM and AR models and is available today at @huggingface @ModelScope2022 and at our website


Apollo retweeted

We're expanding our partnership with @USGSA. Under a new OneGov agreement, we are bringing Claude to federal, state, local, tribal, and territorial governments at 40% off.
anthropic.com/news/expanding…

Apollo retweeted
Over the past few months, Anthropic scientists have engaged in deep research partnerships with six organizations developing new medicines. We've also begun drug discovery efforts of our own.
In doing so, we’ve learned much more about how Claude can support the many stages of drug development.
In this blog post, we share some early results from these efforts, and describe how this work fits in with our wider ambitions in the life sciences.
anthropic.com/research/early…

Apollo retweeted

Introducing FrontierCode 2.0: our new coding benchmark that measures a model’s ability to go beyond the spec.
Most coding evals measure a model’s ability to write code that meets a spec. With FrontierCode 1.0, we asked a new question: would you actually merge the PR?
FrontierCode 2.0 is comprised of more diverse tasks, featuring larger scopes and higher mergeability standards. We are now asking: not only would you merge this PR, but should you?
One key feature of FrontierCode 2.0 is underspecified prompts. Rather than including every engineering decision, prompts are deliberately ambiguous, giving the models room to demonstrate their judgment.
The result is a benchmark that is far from saturated, with the top model scoring just 45%.

Apollo retweeted

Today we announce the launch of the Giotto family of models. We are unveiling Giotto Alto and Giotto Solo, the smartest European sovereign AI models on the market.
Giotto Alto is our flagship model built for advanced reasoning capabilities, free for everyone and available on the App Store and Google Play. It is hosted on European cloud infrastructure, so your data stays in Europe. Giotto Solo is the smartest model that runs on a single GPU, so organisations can keep their AI on their own infrastructure.
We are a Swiss lab with a European heart and we built this so that Europe can run advanced AI on its own terms.
Use Giotto: cloud.giotto.ai/

Readers added context they thought people might want to know
Giotto's graphic shows self-reported benchmark scores comparing to specific variants of other models; independent leaderboards as of late Oct 2026 list no Giotto and different leading scores on AIME 2026, GPQA-Diamond and HLE.
giotto.ai
benchlm.ai/benchmarks/aim…
benchlm.ai/benchmarks/gpq…
benchlm.ai/benchmarks/hle
RT @reflection_ai: We ran ~1.3 billion sandboxes in our largest RL run for Beam - spanning RL training, evaluation, and ablations. With eva…
Apollo retweeted

Carbon-X is the first model achieving frontier intelligence on DNA understanding!
It is fluent in both English and DNA so you can chat to DNA!
Biology and DNA understanding will have a huge impact and be the main focus of the frontier labs.
Model: huggingface.co/HuggingFaceBi…

Apollo retweeted

MAI Gym 🔥 New 9B model that can operate both phones and computers, from Alibaba Tongyi MAI team
- Apache 2.0
- Sim-to-real RL: 28.8% > 48.1% task success
- Up to 20K parallel training environments
- Reported SOTA among open GUI agents under 10B

Apollo retweeted

This is Genie 4, our most realistic and interactive world model yet. 🌐
Explore dynamic environments in real time to see how the scene responds, sounds, and how the people in it move, react, and speak.
Apollo retweeted
After its 4B model, @SparkLLM is back again with an even smaller one: Spark-X2.6-1.7B
- 3 thinking modes: none, low & high
- Up to 1M context
- Apache 2.0 + GGUF/int4/int8/FP8
- Leading decoding throughput vs similarly sized models in reported tests

Apollo retweeted

Can a 27B model push the Pareto frontier of autonomous research and beat 1T–2.8T giants?
Meet AREX-2 (27B), spearheaded by BAAI in collaboration with USTC and RUC (built on Qwen3.8-27B). Turning Recursive Self-Improvement (RSI) into a practical test-time scaling paradigm, we pinpoint two keys to self-evolution: Deep Reflection & Long-Horizon Execution. By reinforcing algorithmic optimization tasks, AREX-2 emerges with exceptional deep reflection and long-horizon execution capabilities—significantly boosting its performance oncomplex coding and deep research to top MLE-bench Lite (81.8) and set new ≤40B SOTA on BrowseComp (84.0) & HLE (52.6)👇

Apollo retweeted

Microsoft's MAI-Image-2.7-Preview takes #2 on AA-Image-Editing v2.1, close behind OpenAI's GPT Image 2.5 Sunburst (max) and a clear step up from MAI-Image-2.6
MAI-Image-2.7-Preview is Microsoft AI's newest image editing model, succeeding MAI-Image-2.6, released in August.
In our testing, MAI-Image-2.7-Preview scores higher than MAI-Image-2.6 on all 7 editing actions we measure, and ranks #1 on 4 of them: Scene & Style Edit, Text or Symbol Edits, Reasoning-Based Edit, and Enhancement & Restoration. This new model improves on MAI-Image-2.6 with the biggest gains in Composition & Framing (+57 Elo), Text or Symbol Edits (+49) and Scene & Style Edit (+48). We see its best use cases to be in Live-Action Film, Consumer and Frontier edits, where it ranks #1.
MAI-Image-2.7-Preview is available today in MAI Playground for image editing only, with text to image stated to be coming soon.
Congratulations to @MicrosoftAI on the release!
See below for our detailed analysis and example outputs of MAI-Image-2.7-Preview in the Artificial Analysis Image Arena 🧵
Apollo retweeted

Introducing Echo-3. A state-of-the-art world model.
Echo-3 turns phone captures into photorealistic, metric-scale 3D worlds. From a single room to multi-floor buildings, outdoor and public spaces.
Available today.
Apollo retweeted
Interesting models from a community member 👀
Groot Series 4 MoE models ranging from 19B to 280B
✨ 19B/A3B
128K context on a 16GB GPU, outperforming larger models on reported benchmarks
✨ 65B/A6B
28% fewer output tokens vs Qwen3.8 Flash Next
✨ 238B/A18B
Beats larger models on 6 agentic benchmarks, with 1M context
✨ 280B/A16B
- 63.47 on SWE bench Pro
- $0.13/task on DeepSWE 1.1
- Adjustable reasoning effort

Apollo retweeted

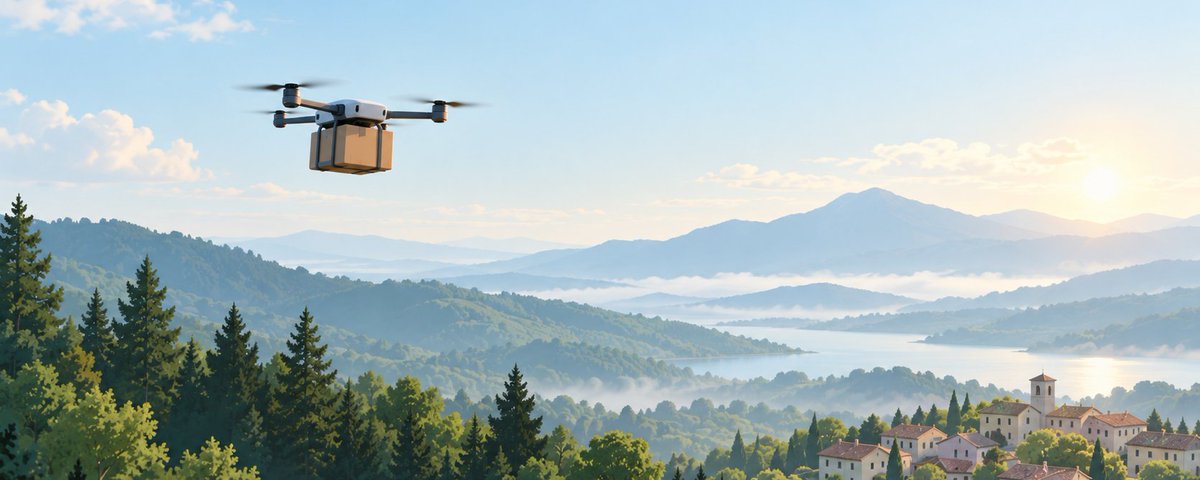
Meituan opened its first mountain-village drone route, flying 5.3 km up to Dongshan Village near Ningbo instead of a 12 km winding road and cutting delivery from close to an hour to about 20 minutes. @meituan
Apollo retweeted

DeepSeek V4.1 Flash 1017 on 4x DGX Sparks
SGLang vs TensorFold
Both are my recipes. Tests done by @kevintheoo.


Apollo retweeted

Announcing three major scientific discoveries, one each in mathematics (harmonic analysis), computer science (complexity theory), and physics (quantum field theory).
AI starting to help us improve our understanding of the universe! openai.com/index/building-sc…
