

Founder, President & Chief Scientist @PrunaAI Prev. @Twitter research, Ph.D. in ML @TU_Muenchen
Joined January 2019
- Tweets716
- Following188
- Followers764
- Likes1.9K
Bertrand Charpentier retweeted

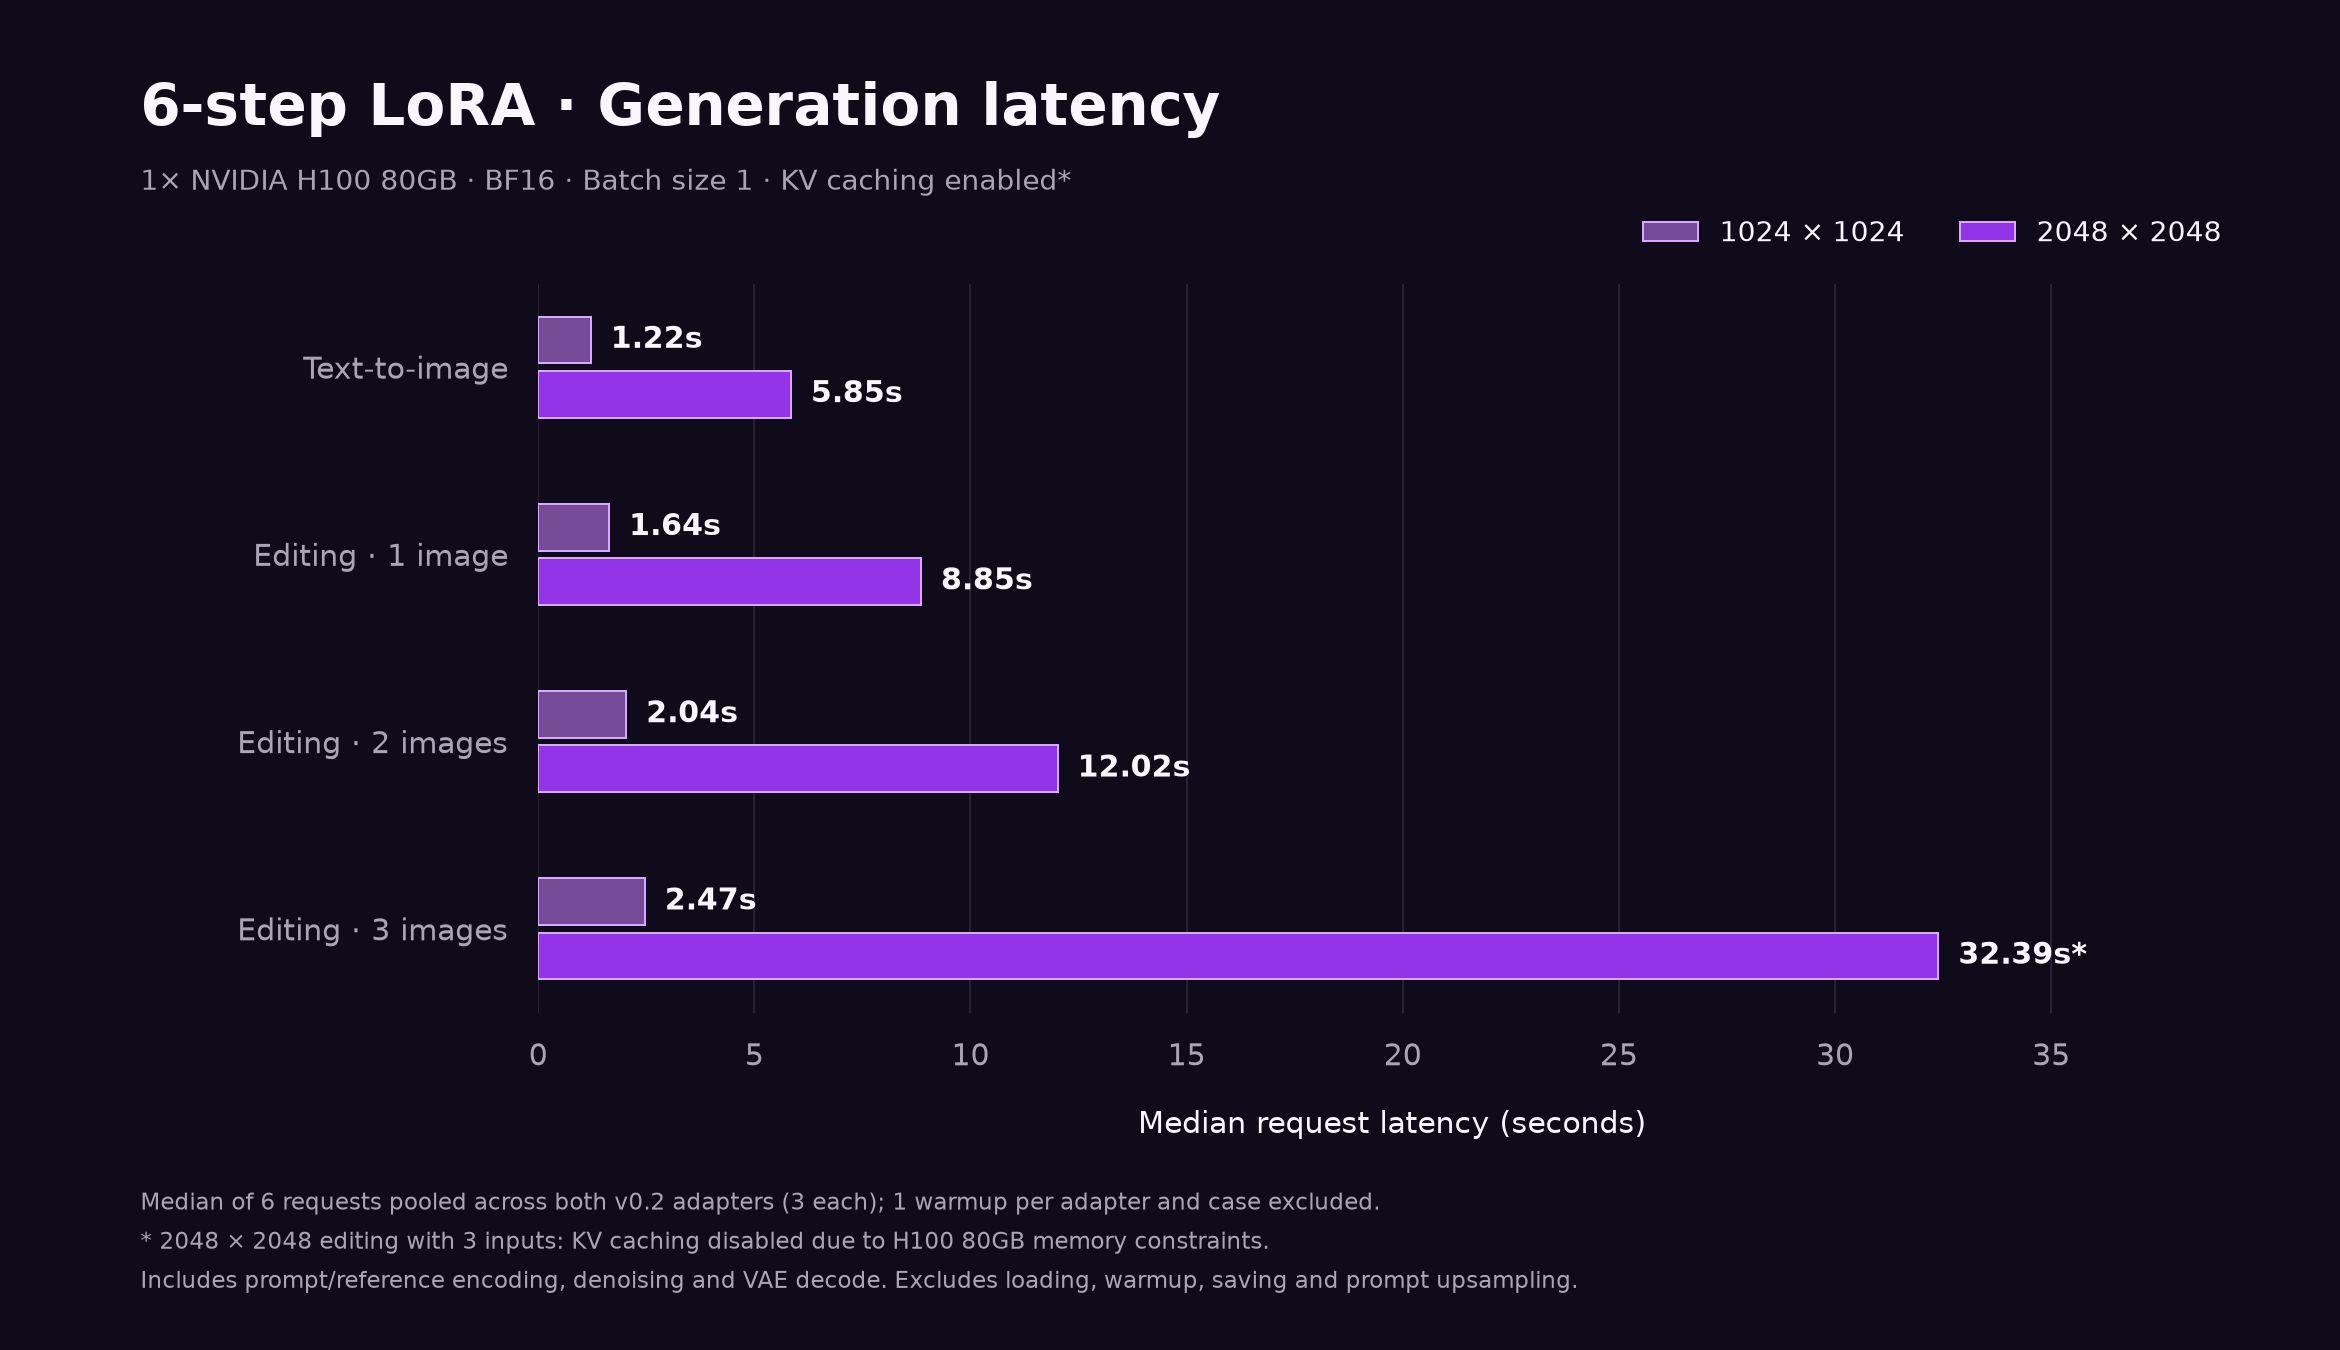
P-Q-Image-2.1 brings Qwen-Image-2.1 generation and editing down to six steps, with no CFG and up to 6.3× faster generation.
🤖 modelscope.ai/models/PrunaAI…
⚡ Six steps, same workflow: The v0.2 LoRA adapters run on top of Qwen-Image-2.1 while keeping its base pipeline, text encoder, and VAE unchanged.
🖼️ Generate or edit: Use one adapter for text-to-image generation and single- or multi-image editing, with up to three reference images.
✨ Skip the separate prompt-upscaling pass: The 6-steps-upsampled variant incorporates prompt-upscaling benefits into the adapter, reducing end-to-end generation time from a short prompt.
🎛️ Choose the trade-off: Use 6-steps for behavior closer to the base model, or 6-steps-upsampled when prioritizing visual quality from concise prompts.
🛠️ Built for the Qwen stack: Start at 1024 × 1024 and use the matching six-step schedule. Higher resolutions may work, but were outside the adapter’s training coverage.
📜 Qwen Research License Agreement. This is a LoRA adapter, not a standalone model; it requires the Qwen-Image-2.1 base weights.

Bertrand Charpentier retweeted

Talking-avatar videos are getting faster and more affordable. According to @PrunaAI benchmark, P-Video-2-Pro-Avatar ranked #1 in overall human evaluation at 768p, runs up to 3× faster, and costs 7× less at 480p.
Starting at $0.02 per second. Ideal for UGC, ads, and music videos.

P-Video-2-Pro-Avatar is #1 in overall human ratings, at a fraction of the cost and in seconds.
- Quality: #1 of 10 models at 768p
- Cost: 7× cheaper, just $0.02/s vs $0.14/s at 480p
- Speed: 3× faster, just ~9.7s for a 10s clip at 480p
- # 1 for music videos at 768p and #2 at 480p
Across both Quality × Price and Quality × Speed, P-Video-2-Pro-Avatar stands out in the high-quality, low-cost, fast-generation region.
From UGC ads to music videos, create high-quality talking avatars without compromising on speed or budget.
Benchmarked by @RapidataAI.
🧩 API & Playground: buff.ly/OHtx3eM
📚 Documentation: buff.ly/bHQHKV0
📊 P-Bench: buff.ly/Fk54Z2K


Bertrand Charpentier retweeted

One portrait + one script = a talking video with natural expressions and accurate lip sync. No camera, no studio.
@PrunaAI P-Video-2-Pro-Avatar: from $0.02/s, 50% off until Nov 5, 18:00 CET.
Full details 👇
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

Pruna P-Video-2-Pro Avatar will be available in ComfyUI!
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

cuando descubres que puedes convertir cualquier foto de tus amigos en un vídeo hablando
EL GRUPO DE WHATSAPP NO VA A SOBREVIVIR A ESTO
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted
A single photo can become a video of a talking avatar, complete with natural expressions and lip-syncing.
P-Video-2-Pro-Avatar also supports audio alone or speech from text, up to 3 minutes. It's interesting to create content without needing to re-record it.
The 50% launch discount is valid until November 5.
@PrunaAI
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

ceo: how much did that 60 second avatar video cost
me: $1.20
ceo: per second??
me: for the whole video
list price. $0.60 during the 2 week launch window
🤝 Paid partnership
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

el ceo de anthropic viendo que ahora puedes subir tu propio audio y que el avatar lo siga exacto sin desincronizarse
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

I can't believe what they say on this talk show 👀
By P-Video-2-Pro-Avatar
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

One image. Two ways to bring it to life.
P-Video-2-Pro-Avatar is here!
Powered by MiniMax H3, delivering realistic expressions, natural motion, and accurate lip-sync from a single portrait.
Your image. Your voice. Your story.
This is where AI avatars get REAL.
@PrunaAI
🤖 Made with AI
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

P-Video-2-Pro-Avatar is live 🚀
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

This week we're reviewing your 𝗣𝗿𝘂𝗻𝗮 𝗖𝗿𝗲𝗮𝘁𝗶𝘃𝗲 𝗣𝗿𝗼𝗴𝗿𝗮𝗺 ✨ applications! Hurry up and apply now to be considered!
- 𝗪𝗵𝗮𝘁’𝘀 𝗶𝘁 𝗮𝗯𝗼𝘂𝘁? A space for AI artists and creators to experiment with faster, more affordable, and controllable models.
- 𝗪𝗵𝗼’𝘀 𝗶𝘁 𝗳𝗼𝗿? The program is open to artists, filmmakers, animators, designers, developers, creative technologists, and AI-native creators.
- 𝗪𝗵𝗮𝘁 𝗱𝗼 𝘆𝗼𝘂 𝗴𝗲𝘁? Become an 𝗘𝘅𝗽𝗹𝗼𝗿𝗲𝗿 or a 𝗙𝗲𝗹𝗹𝗼𝘄 and get supported with monthly credits, early model access, monthly paid campaigns, and opportunities to be featured.
Just original concepts. Share your style with creative freedom and hundreds of possibilities.
Read more information and apply here: pruna.ai/blog/pruna-creative…
Bertrand Charpentier retweeted
First test of P-Video-2-Pro-Reference, using my character sheet as a visual reference for a 15-second, 16:9 fashion clip.
Fun to see a character design move from a static reference into video. Looking forward to trying more reference combinations. @PrunaAI
Introducing P-Video-2-Pro-Reference based on @MiniMax_AI H3! 🎬
Combine images, videos, and audio references to guide how your video looks, moves, and sounds. Keep characters consistent, transfer motion, and bring different visual elements together in a single generation.
• 𝗜𝗻𝗽𝘂𝘁: Text prompt with image and/or video references, plus optional audio
• 𝗥𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲𝘀: Up to 9 images, 3 videos, and 3 audio files
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s at 480p or 768p
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: Output starting at $0.015/s in Cost mode, with reference inputs billed separately
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First and last frames, seed, aspect ratio, and prompt upsampling
Two modes: Speed and Cost. Choose the trade-off that fits your workflow.
Available via our inference partners @Cloudflare, @scenario_gg, @replicate, @WiroAI, @TellersAI, @eachlabs, @wavespeed_ai, @inference_sh, @_segmind, @togethercompute, @EdenAIco, and @runware
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login
Bertrand Charpentier retweeted
Munich, join us for Hacktoberfest with @MLHacks !
We're hosting a casual meetup at the Pruna office on October 29!
Come grab a pizza, have a drink, meet other developers, and chat about open source, side projects, or whatever you're building.
No talks or pitches, just a relaxed evening with the local community.
📍 Pruna office, Munich
📅 October 29, 6–9 PM
Hope to see you there!
👉 Sign up: events.mlh.com/events/15374-…

Bertrand Charpentier retweeted

AI VIDEO STILL LOSES YOUR CHARACTER BETWEEN SHOTS.
@PrunaAI released P-Video-2-Pro Reference for that. you give it up to 9 images, 3 videos and 3 audio files as references, and it keeps the subject consistent through the clip. built on MiniMax H3.
it can also copy the motion from a reference video, or mix elements from different references in one generation.
output starts at $0.015 per second in cost mode, with references billed on top. the API is live now.
🤝 Paid partnership
Introducing P-Video-2-Pro-Reference based on @MiniMax_AI H3! 🎬
Combine images, videos, and audio references to guide how your video looks, moves, and sounds. Keep characters consistent, transfer motion, and bring different visual elements together in a single generation.
• 𝗜𝗻𝗽𝘂𝘁: Text prompt with image and/or video references, plus optional audio
• 𝗥𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲𝘀: Up to 9 images, 3 videos, and 3 audio files
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s at 480p or 768p
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: Output starting at $0.015/s in Cost mode, with reference inputs billed separately
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First and last frames, seed, aspect ratio, and prompt upsampling
Two modes: Speed and Cost. Choose the trade-off that fits your workflow.
Available via our inference partners @Cloudflare, @scenario_gg, @replicate, @WiroAI, @TellersAI, @eachlabs, @wavespeed_ai, @inference_sh, @_segmind, @togethercompute, @EdenAIco, and @runware
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

p-video-2-pro-reference by @PrunaAI is now available on Design Arena!
Built on @MiniMax_AI H3, p-video-2-pro-reference combines image, video, and audio references to give creators greater control over video generation. It supports consistent characters, motion transfer, and multimodal inputs, with adjustable duration, aspect ratio, and first and last frames.
Congrats to the @PrunaAI team on the launch!

Introducing P-Video-2-Pro-Reference based on @MiniMax_AI H3! 🎬
Combine images, videos, and audio references to guide how your video looks, moves, and sounds. Keep characters consistent, transfer motion, and bring different visual elements together in a single generation.
• 𝗜𝗻𝗽𝘂𝘁: Text prompt with image and/or video references, plus optional audio
• 𝗥𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲𝘀: Up to 9 images, 3 videos, and 3 audio files
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s at 480p or 768p
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: Output starting at $0.015/s in Cost mode, with reference inputs billed separately
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First and last frames, seed, aspect ratio, and prompt upsampling
Two modes: Speed and Cost. Choose the trade-off that fits your workflow.
Available via our inference partners @Cloudflare, @scenario_gg, @replicate, @WiroAI, @TellersAI, @eachlabs, @wavespeed_ai, @inference_sh, @_segmind, @togethercompute, @EdenAIco, and @runware
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

ai video was never the hard part
keeping your product looking the same in every shot was
@prunaai just dropped p-video-2-pro reference and it locks your product, character or voice straight from your refs
up to 9 images, 3 videos and 3 audio clips, sound included
from 2 cents a second
consistent ai video just got cheap
API📍dashboard.pruna.ai/login
🤝 Paid partnership
Introducing P-Video-2-Pro-Reference based on @MiniMax_AI H3! 🎬
Combine images, videos, and audio references to guide how your video looks, moves, and sounds. Keep characters consistent, transfer motion, and bring different visual elements together in a single generation.
• 𝗜𝗻𝗽𝘂𝘁: Text prompt with image and/or video references, plus optional audio
• 𝗥𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲𝘀: Up to 9 images, 3 videos, and 3 audio files
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s at 480p or 768p
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: Output starting at $0.015/s in Cost mode, with reference inputs billed separately
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First and last frames, seed, aspect ratio, and prompt upsampling
Two modes: Speed and Cost. Choose the trade-off that fits your workflow.
Available via our inference partners @Cloudflare, @scenario_gg, @replicate, @WiroAI, @TellersAI, @eachlabs, @wavespeed_ai, @inference_sh, @_segmind, @togethercompute, @EdenAIco, and @runware
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login
Bertrand Charpentier retweeted

PRUNA JUST DROPPED THE MOST CONSISTENT AI VIDEO MODEL I'VE TESTED AND I'M GOING TO EXPLAIN WHY.
Same surfer. Same board. Every single angle.
This is P-Video-2-Pro Reference by @PrunaAI.
References → Prompt → Locked Subject → Video With Sound.
→ You send up to 9 images, 3 videos and 3 audio clips.
→ It locks your subject: a character, a product, a clip or a voice.
→ It returns an MP4 at 24 fps with generated sound.
→ Clips go from 5 to 15 seconds at 480p or 768p.
→ Built on MiniMax H3 Ref2V.
Consistency was always the weak spot of AI video. Not anymore.
Introducing P-Video-2-Pro-Reference based on @MiniMax_AI H3! 🎬
Combine images, videos, and audio references to guide how your video looks, moves, and sounds. Keep characters consistent, transfer motion, and bring different visual elements together in a single generation.
• 𝗜𝗻𝗽𝘂𝘁: Text prompt with image and/or video references, plus optional audio
• 𝗥𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲𝘀: Up to 9 images, 3 videos, and 3 audio files
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s at 480p or 768p
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: Output starting at $0.015/s in Cost mode, with reference inputs billed separately
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First and last frames, seed, aspect ratio, and prompt upsampling
Two modes: Speed and Cost. Choose the trade-off that fits your workflow.
Available via our inference partners @Cloudflare, @scenario_gg, @replicate, @WiroAI, @TellersAI, @eachlabs, @wavespeed_ai, @inference_sh, @_segmind, @togethercompute, @EdenAIco, and @runware
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login