
Research Scientist @GoogleResearch | PhD @TechnionLive | NLP
Joined June 2022
- Tweets368
- Following796
- Followers475
- Likes708




[1/7] Why do frontier LLMs make factual errors?
Is it because they never learned the fact…
or because they can’t access knowledge they already encoded?
In our new paper, we show:
The bottleneck is not encoding; it is recall. 🧵👇
Paper: arxiv.org/abs/2602.14080
Many thanks to @_galyo @bd_eyal @zorikgekhman @eran_ofek59358 @GoogleResearch

Nitay Calderon retweeted

1/ In 2023 I went back to academia for my PhD with one thought in mind: what could we do with a GPT-like creature that simulated dementia?
The thought didn't let go. And now, the paper is out.
Meet DeLMs- Dementia Language Models 🧠
Nitay Calderon retweeted

The gap between frontier models' ability to derive clearly superhuman results and their absolute lack of ability to write about them in a human legible way is IMO the best current example of the "jagged frontier"

I'm annoyed by how badly LLMs write technical papers, even with a human in the loop and many rounds of iteration, given how good they are at reading/criticizing/evaluating papers.
I've tried Codex + Sol/Astra, Claude Code + Fable 5.2, and Claude Code + Astra. Even after repeatedly editing, steering, and asking for rewrites, a quarter of paragraphs are still barely human-readable and need substantial rewriting.
Curious what people are actually using for LLM-assisted paper writing these days 🤔
Nitay Calderon retweeted

🚨 Can AI assistants understand social situations only from the user’s description? And how can we test this when we often don’t know what really happened?
We tackle this using multi-agent simulations with verifiable ground truth 🎯
More details in @TaubenfeldAmir’s thread 👇

Nitay Calderon retweeted
As an author of one of the 15 audited benchmarks, some personal thoughts on this:
1. There’s such a tight loop today between measurement and optimization, that high profile benchmarks materially impact what counts as progress in our field. This really raises the stakes on benchmarking work, and makes the difficult and not very glamorous work of re-examining existing benchmarks with critical (and impartial) eyes extremely, extremely valuable. I’m really glad to see @EpochAIResearch starting this initiative, congrats.
2. On the other hand, as someone working on frontier evals for the past few years, I want to emphasize how virtually impossible it is to put out a flawless benchmark. And it gets meaningfully harder the wider the scope of the benchmark is and the more agentic the task is.
3. I don't think it's helpful to view benchmarks as binary good vs bad, “flawed” vs “verified”. Auditing them, finding problems and improving on those problems is better viewed as a continuous process. In some sense it inevitably is, because some grading problems only become apparent when models become capable enough to utilize them, and are really hard to forsee in advance.
4. The wider the participation in this process will be, and the more parties that have a stake in these benchmarks, the better the outcome will be for the entire community.
5. This is essentially what we tried to do with SimpleQA Verified: we used OpenAI’s SimpleQA internally for some of our factuality work, realized it has a lot of issues, improved on them as much as we could at the time, and put the revised benchmark back out in the hands of the community. Based on my personal experience working with some of the other benchmarks audited by Epoch AI that were found as problematic, this can work just as well on them too.


Nitay Calderon retweeted

Today @GoogleDeepMind and @GoogleResearch are introducing WeatherNext 3 ✨ Our most advanced and accurate AI weather model now learns directly from real-time observations, enabling it to provide timely and more localized predictions for the weather events that impact people the most.
WeatherNext 3 now includes real-time satellite data, hourly refreshes, higher resolution, precise precipitation forecasting, and clean energy variables.
Some of the key aspects of this release in 🧵👇

Nitay Calderon retweeted

Now accepted to #EMNLP2026!

Can AI agents read a social science paper and write the code from scratch to reproduce its results?
No access to original code. Just text + data.
New paper with Ben Kohler, @david_rzs, @__jae_1, and @miserlis_
👇

Nitay Calderon retweeted

Introducing Gemini 3.7 Flash : )
- it is fast!
- 50% lower price than 3.6 flash (through end of year)
- strong intelligence increase in only ~3 weeks (thanks to some awesome algorithmic improvements)
- available in the API, AI Studio, Antigravity, and more!


Nitay Calderon retweeted

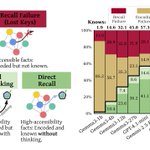
Today we discuss knowledge profiling, a behavioral framework that measures both encoding and recall, and use it to examine the underlying bottlenecks of factuality in frontier LLMs. Read more →goo.gle/4wXia92

ALT Five knowledge profiles that characterize facts.
Nitay Calderon retweeted

Mythos01 ranking 1st after 72 hours of the GLEE Competition!
Come build AI Agents that negotiate, persuade, and bargain: glee-competition.com
There is a GLEE competition paper track in IAB@NeurIPS2026, and also 6000$ prizes for the best agents!

Nitay Calderon retweeted
The GLEE Competition launched just 24 hours ago, and participants’ agents have already played more than 20,000 games!
Build an AI agent that can bargain, negotiate, and persuade other agents or humans, and compete for US$6,000 in prizes.
glee-competition.com

Nitay Calderon retweeted

New paper at CL!
Eye Tracking Based Cognitive Evaluation of Automatic Readability Assessment Methods
TLDR: existing readability assessment methods (including LLMs) are poor predictors of reading ease.
Paper: lnkd.in/eEkYPJ3v
Image: a readability formula from 1948 in use


Great position:
arxiv.org/abs/2507.00163
@universeinanegg

Great post!!
I agree with every point.
Also wanted to join the well-deserved hype around tau, which is IMO the foundational benchmark/approach for evaluating tool conversational agents.
We recently built on your work and published a paper on challenges your wrote about, synthetic data generation to extend tau, which is already saturated (except banking).
Hope you find it interesting, and I'll be happy to talk
arxiv.org/abs/2605.28556

Nitay Calderon retweeted

Excited to share my new paper from my internship at Google Research! 🌍
We present Multilingual-IRT, extending Item Response Theory to parallel multilingual benchmarks for cheaper and more meaningful multilingual evaluation.
Check it out! gililior.github.io/multiling…
🧵1/8
