


Albert Gu retweeted

Releasing FLAT: Flash Linear Attention on TPUs 🚀
Pallas training kernels for Linear Attention, Mamba-2 and GLA. On one TPU v6e, forward + backward is up to 3x faster than FLA on an H100 for GLA, and 1.5x faster for Mamba-2.
🧵

Albert Gu retweeted

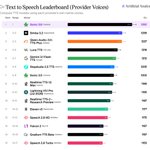
Cartesia Sonic-3.6 is the #1 TTS model on the Voice Arena US English 🇺🇸 Leaderboard.
It debuts at 1085 Elo, in a statistical tie with Google DeepMind's Gemini 3.1 Flash TTS, and ahead of its own Sonic-3.5, Simba 3.2 and Grok TTS. It holds the top spot as a real-time model.
Sonic-3.6 is the latest TTS model from @cartesia. The model has been highly preferred among raters on @voicearena_ai.
Results backed by 1,400+ blind, head-to-head listener votes across two languages 🧵

Albert Gu retweeted

Introducing Sonic-3.6: our most lifelike TTS yet, and another step change in naturalness across 44 languages. Just three months after our Sonic-3.5 launch, we've made fundamental model improvements based on feedback from the teams building on Sonic.
We're #1 on @ArtificialAnlys across both the provider and controlled voice streaming leaderboards — best-in-class voices + the best underlying model.
Available in beta today. Hear it for yourself 👇


Albert Gu retweeted
A very happy 80th Independence Day to India, from team Cartesia! 🇮🇳
Coming closer to home with Sonic 3.6, we're making every one of India's languages more natural, expressive, and accurate:
- Hindi that flows the way you speak it
- Hinglish that switches without missing a beat
- Naturalness gains across all 9 existing Indic languages
- Plus two new languages: Urdu and Odia
Every voice in this video generated by Sonic.
Albert Gu retweeted

Excited that @cartesia is in @cursor_ai's India campaign with some of the most ambitious founders of Indian origin (including in Delhi where I grew up)
featuring amazing folks @amanrsanger, @vipulved, @tankots, @mukundjha, @ManishaRaisingh, @regards_rishi, @_sankyy

Albert Gu retweeted
Our London office is growing quickly, reach out to @_albertgu or me if you’d like to work on a very different, new and exciting research agenda to advance multimodal models

Good night DeepMind. Wow.
FT: "Google is shifting control of its AI effort from London back to Silicon Valley"
"executives and board members remained concerned by its weaker position in coding models and enterprise AI, where Anthropic and OpenAI have established an early lead."
"Several current and former DeepMind employees said the reorganisation had sent shockwaves through the London-based lab, with some fearing it marked the end of the research culture that Hassabis has long protected. One former DeepMind executive at a rival company said they had already received calls from multiple staff who said they were ready to jump ship."
"Over the past year, Hassabis has devoted more time to Isomorphic Labs, the AI drug discovery company he founded"
Albert Gu retweeted
.@_albertgu and I are organizing a research happy hour in London on Monday July 13th.
Come hang out!
luma.com/3p1u9pgf

Albert Gu retweeted

We will be at ICML in Seoul to present dnaHNet in Oral + Poster sessions! Swing by and say hi if you wanna learn about the current SOTA in DNA foundation models :)
Oral session: Hall D2 at 10 AM, Jul 7
Poster session: Hall A #900 at 2 PM, Jul 7

Most genomic AI models use fixed rules to process DNA into chunks, imposing arbitrary boundaries on a sequence with its own biological structure.
@arnavshah0, @victor_ljz, and team developed dnaHNet, a tokenizer-free foundation model that learns its own segmentation from scratch, supervised by @_albertgu, @genophoria, and @BoWang87.


Albert Gu retweeted
Two new models just dropped 👀
Sonic-3.5 and Ink-2 are the #1 streaming models for text to speech and speech to text

Albert Gu retweeted

probably a bit late to the party, but i will be interning at @cartesia over the summer -- working on model architectures with @nimit_sohoni and @_albertgu
super excited! :))

Albert Gu retweeted

🧵 on some fun insider details on ink-2 😼

Cartesia Ink-2 debuts as #1 for accuracy on the brand-new streaming speech-to-text leaderboard from @ArtificialAnlys! We designed Ink-2 from the ground up for voice agents - with low latency, eager transcripts, and semantic endpointing.

Albert Gu retweeted

Today, @MichaelElabd, @QuantumArjun, and I are excited to announce Trajectory.
We are a research lab and product company building the platform for Continual Learning.
Our platform unlocks the signal already sitting in product usage, so companies can continuously post-train large-scale agentic models that outperform the frontier. @trajectorylabs
We’ve raised $15M from @Conviction, @BessemerVP, @radicalvcfund, @jeffdean, @drfeifei and more.
We’re partnering with some of the best AI-native companies: @ClayRunHQ @Harvey, @DecagonAI, @mercor, @RogoAI to power their agentic systems, some of which we are already in production with.
We’ve brought together a world class research team from DeepMind, OpenAI, Apple, Meta Superintelligence, Amazon AGI, Scale AI, and an elite product team from Stripe and Figma.
AI will never again start on day one. Every correction, every retry, every edit will make products smarter. This is Continual Learning.
Albert Gu retweeted

After some mathematical rewrite, turns out all of transformer is a series of gemm + epilogue. Given a few optimized primitives, LLMs (and novice humans) can write speed-of-light kernels for all transformer ops!


Albert Gu retweeted

Raven is now also available at fla as well! Enjoy playing with it🐦⬛.
Special thanks to amazing fla team 🎉!
github.com/fla-org/flash-lin…
Albert Gu retweeted

In SuperBPE we found: as tokenizer compression increases, the compute-optimal ratio of train tokens to model params decreases — and remarkably, corresponds to the same underlying ratio of train *bytes* / param! Our new work makes it official: scaling laws depend on compression.


Albert Gu retweeted

Attention @arxiv authors: Our Code of Conduct states that by signing your name as an author of a paper, each author takes full responsibility for all its contents, irrespective of how the contents were generated. 1/
Albert Gu retweeted

Higher-Order Linear Attention Models Are RNNs/SSMs:
Generalizing State-Space Duality to higher-order linear attention.
It’s getting wild.
github.com/yifanzhang-pro/HL…

Albert Gu retweeted

SSMs fail on recall tasks they have the capacity to solve. The two dominant approaches today, SSMs and sliding-window attention, both lack persistence: memory either decays over time or gets evicted.
We built Raven to fix this, surpassing all prior linear models even at 16× their training sequence length. 🧵🐦⬛

