
Dance n' Data for Science. Applied AI in Healthcare, Enterprise, and Manufacturing. Always ready to workout.
Joined June 2019
- Tweets149
- Following432
- Followers106
- Likes1.1K



Pinned Tweet
Thrilled to share that our work won the #BestPaperAward at the #SPIEMedicalImaging conference! 🥳 @SPIEtweets 👉arxiv.org/pdf/2005.02231.pdf
Congratulations! to the awesome sauce team led by @jjayaram7 🙌👏 alex karagyris,@follow_kashyap 1/3
#CollabFTW @IBMResearch @Livermore_Comp

Deepta Rajan retweeted

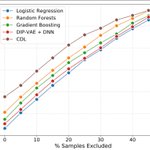
If you are designing Outlier Exposure-free OOD detectors, talk to us at the PODS@ICML workshop. Hint: virtual inlier synthesis + negative data augmentation is the key! @VivekSivaraman1 @RUSH1L @deepdanscience #YamenMubarka @asusensip
Preprint: arxiv.org/abs/2207.05286
4/9

Deepta Rajan retweeted
I will be at #ICML2022 next week! Excited to attend an in-person conference after a long time. Here is a quick roundup of our conference and workshop papers.. If you want to chat about any of our projects, or just meet for coffee, let me know :)
1/9
Deepta Rajan retweeted

i've been submitting my work to conferences for more than 10 years, fighting to make each deadline. i have tried many strategies to cope with the anxiety and make sure that i don't have to work insane amounts of hours on the days before the deadline.
here's what i learned: 👇🧵
Deepta Rajan retweeted
Hot off the press @SciReports: A short thread on TraCE, a new method for post-hoc analysis of chest X-ray models. This can be used to validate model behavior and characterize its weaknesses. Joint work with @kowshik0808 @deepdanscience @pturaga1. Link: nature.com/articles/s41598-0…
ah! the citation problem... 🙄 sigh.

The expressive power of GNNs can be improved by bootstrapping multiple graphs via dropout - An idea that we explored 4 years back (arxiv.org/abs/1704.07487). Interesting to see new theory to support this (arxiv.org/abs/2111.06283). Really wish they atleast cited us!! @RUSH1L
Deepta Rajan retweeted

I spend a lot of “research” time pleading for access to health data
@m_sendhil and I co-founded a new nonprofit, @NightingaleOS, so you don’t have to
We link medical imaging data + ground truth outcomes, and make it available—free!
Launching tomorrow at #NeurIPS2021
This Post is from an account that no longer exists. Learn more
Deepta Rajan retweeted

Congratulations to @jjayaram7, Vivek & the entire team for their collaborative research on Deep Inversion Methods presented at the @NeurIPSConf. @AsuEnergy Ph.D student @VivekSivaraman1 presented the paper last Friday.
@Livermore_Lab
@deepdanscience

Deepta Rajan retweeted

We are hiring research interns (summer 2022, PhD students only)
@MITIBMLab to work in areas such as contrastive learning, density ratio estimation, generative models and tabular data synthesis.
Please DM me your CV if you are interested. #internship
Deepta Rajan retweeted

Do you like data challenges that can push the limits on how #ai impact #care? You are welcome to participate in the two challenges we just launched! You can learn from our own experience in participation in such challenge - see our paper at @NatMachIntell nature.com/articles/s42256-0…


Meeting my fav collaborator after months & celebrating our #Neurips2022 paper on Explainable AI! 🥳 arxiv.org/abs/2109.14274 Checkout our work on counterfactual generation using deep inversion.
Grateful to be a part of this team @jjayaram7 @VivekSivaraman1 join us next time.🙌

Interested in designing counterfactual generators for deep models without access to source data or pre-trained generative models? Check out our #Neurips2022 paper that introduces DISC, a deep inversion technique for this problem. 2/5
arxiv.org/abs/2109.14274

1
9
Deepta Rajan retweeted

"Ideas are free/cheap, but implementing them is the real work" is just a way of devaluing the work of people who are very good at generating ideas
Deepta Rajan retweeted

Earlier this summer Krystal and I are appointed as ICLR 2022 DEI chairs. Right away we started planning something tangible and actionable to *really* help broaden the ICLR participation pool.
Hence the birth of CoSubmitting Summer (CSS) program:
blog.iclr.cc/2021/08/10/broa…
1/

It was fun to devour the literature and extract insights with this team! 👏 Congratulations! @JannisBorn @michal_zvi @mariagabrani @drugilsberg @DrKarteris and more.

1/8
What's the role of #AI in medical imaging of #COVID?
We present the largest systematic review, now in @Patterns_CP! Data availability drove AI experts to focus on clinically less relevant tasks + imaging modalities, reducing impact of AI: ibm.biz/ai_cov_img @IBMResearch
6
Deepta Rajan retweeted

On the Role of #AI in Medical Imaging of #COVID19: Systematic meta-analysis
👉largely failed to focus on clinically relevant tasks; recommendations provided
Read More: cell.com/patterns/fulltext/S…
@JannisBorn @deepdanscience @drugilsberg @michal_zvi #100daysofcode #MedTwitterAI #ML

Deepta Rajan retweeted

1/2 🤓Ever wanted to systematically search for publications?📖
We release #paperscraper, a @pypi package for scraping of publication metadata.
It eases publication keyword search & provides endpoints for #PubMed #arxiv #biorxiv #medrixv & #chemrxiv!
Code: ibm.biz/paperscraper
Deepta Rajan retweeted

Lab scientist @jjayaram7 and an @IBMResearch team won an SPIE Best Paper award for their work on a “self-training” deep learning approach to disease diagnosis that can exceed the performance of existing neural networks with 85 percent less annotated data. llnl.gov/news/self-trained-d…
Our proposed small-data learning framework shows that using 85% lesser labeled data, we can build models that match performance of classifiers trained in a large-scale data setting.
We share tricks for handling limited labeled data, class imbalance and multiple conditions. 2/3

