

alignment pretraining @openai | formerly phd @mldcmu, @BrownUniversity
San Francisco
Joined October 2017
- Tweets217
- Following529
- Followers1.3K
- Likes2.8K


Pinned Tweet
Check out @ZihaoZhao1's thread on our new paper!
We compare various techniques to mitigate privacy leakage, finding that synthetic data and LLM rewriting offers a particularly strong privacy/capability trade-off 📈📈

We’ve all offloaded the writing to LLMs, but have you considered REWRITING with LLMs? 👀
Rewriting your private data with an LLM before finetuning gives a better empirical privacy vs. capability trade-off than PII scrubbing or DP-SGD!
To test this, we generated 5,000 synthetic medical records with private information. Then, we finetuned Qwen3.5-4B and gpt-oss-20b with several methods to mitigate privacy leakage and asked two things: does the model learn from the medical records, and does it leak private information?
1/n 🧵👇

Dylan Sam retweeted

1/
When LLMs answer questions with retrieved webpages, several plausible answers may appear.
What if one appears much more often and fits much of what the question asks, but still isn't the right answer?
Excited to share our #EMNLP2026 paper on this!
📄arxiv.org/abs/2610.27114

Dylan Sam retweeted

We’ve all offloaded the writing to LLMs, but have you considered REWRITING with LLMs? 👀
Rewriting your private data with an LLM before finetuning gives a better empirical privacy vs. capability trade-off than PII scrubbing or DP-SGD!
To test this, we generated 5,000 synthetic medical records with private information. Then, we finetuned Qwen3.5-4B and gpt-oss-20b with several methods to mitigate privacy leakage and asked two things: does the model learn from the medical records, and does it leak private information?
1/n 🧵👇
Dylan Sam retweeted

We're hiring safety researchers at @thinkymachines! 🦺
My team works on safety across the model development stack -- pre-training data filtering, harmful capability evals, safety post-training, red-teaming, abliteration/malicious fine-tuning.
We're particularly interested in building evals and tooling to make strong safety cases for open-weights releases. We think this is where some of the most important safety research will happen in the next few years.
If any of this resonates, apply here: jobs.ashbyhq.com/ThinkingMac…

Dylan Sam retweeted

A lot of excitement in synthetic data for science is motivated by ambitious uses of LLMs (e.g., running a survey with GPT before real participants, forecasting promising experiments with LLMs). We ask, what beliefs should the experimenter have to make this a good idea? 🧵

Dylan Sam retweeted
9/ This work was done with the amazing @brwilder. I will be presenting this work today at #ICML 🇰🇷 (Thursday 5:00-6:45 PM KST) in Hall A #3605. Feel free to stop by or reach out to chat! Would love to meet old/new friends! :)
Paper Link: arxiv.org/abs/2607.06656

Really excited to see work developing understanding of when we are guaranteed to benefit from LLMs and synthetic data!! 📈


Dylan Sam retweeted

Thanks for having me! I talked about our work on valid inference with synthetic data (arxiv.org/abs/2508.06635) and robust human-AI complementarity (ICML 2026, paper up soon), both with my PhD student @yewonbyun_


Dylan Sam retweeted

New OpenAI post: Can midtraining on docs about aligned AI bake in alignment priors for agents? We report an experiment where those priors are quickly washed away by RL and fail to generalize to agentic settings. But that cuts both ways: priors that AIs are misaligned fade too!

Dylan Sam retweeted

I'm also extremely excited for our companion post today on Model Spec Evals! Spec Evals are a new way we're measuring progress towards alignment with the Model Spec — including public results, an open dataset, and code others can build on.
alignment.openai.com/model-s…
Dylan Sam retweeted

As AI agents access more untrusted information with greater autonomy, prompt injections may become the greatest security challenge of our era.
@GraySwanAI, in collaboration many frontier labs, just released our paper on the largest public prompt injection challenge to date.
🧵

Your AI agent can be hijacked by a prompt injection and you'd never know!
The attack executes. The response looks normal. And the user moves on.
We ran the largest public competition testing this exact threat across tool use, coding, and computer use agents. 464 participants, 272K attacks, 13 frontier models. Every model proved vulnerable.


I defended my PhD thesis!
Also, a very (~4 month) late life update, but I've joined @OpenAI to work on safety research and pretraining safer language models! 📈
Thank you to my advisor @zicokolter and my committee: Matt Fredrikson, @andrew_ilyas, and @furongh! 🙏

Dylan Sam retweeted

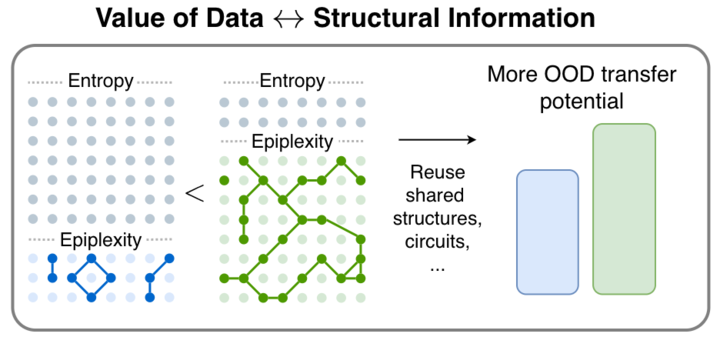
1/🧵 We are very excited to release our new paper! From Entropy to Epiplexity: Rethinking Information for Computationally Bounded Intelligence
arxiv.org/abs/2601.03220
with amazing team @ShikaiQiu @yidingjiang @Pavel_Izmailov @zicokolter @andrewgwils
Next, I'm presenting on safety pretraining, where we find that incorporating safety behaviors during pretraining leads to more robust language models!
Come by Poster #5210 at Exhibit Hall C,D,E at 4:30pm today (12/4)!
xitter.cf/dylanjsam/status/19679…


Finally, I'm presenting work on monitoring models for harmful behaviors, hallucinations, and adversarial manipulation at Poster #1304 in Exhibit Hall C,D,E on 12/5 at 4:30pm!
xitter.cf/dylanjsam/status/18799…
To trust LLMs in deployment (e.g., agentic frameworks or for generating synthetic data), we should predict how well they will perform. Our paper shows that we can do this by simply asking black-box models multiple follow-up questions! w/ @m_finzi and @zicokolter
1/ 🧵

Dylan Sam retweeted
I’m at NeurIPS this week (12/2-12/8) to present our work on when/how synthetic data (e.g., LLM simulations) can help scientists make inferences with less real data, improving the efficiency of costly experiments. Come by Poster #904 on Thursday 4:30PM (Exhibit Hall C,D,E)!🙂
